Chaos Engineering Basics
Part of the DevOps Roadmap
In short
You have a backup database, auto-restarts and retries. Have you seen them actually work? Chaos engineering breaks things on purpose, carefully, so you find out on a calm Tuesday, not mid-outage.
Deliberately injecting failures into a system (killing a server, adding network latency) in a controlled way to verify it actually handles failure gracefully, rather than assuming it does.
Think of it like this
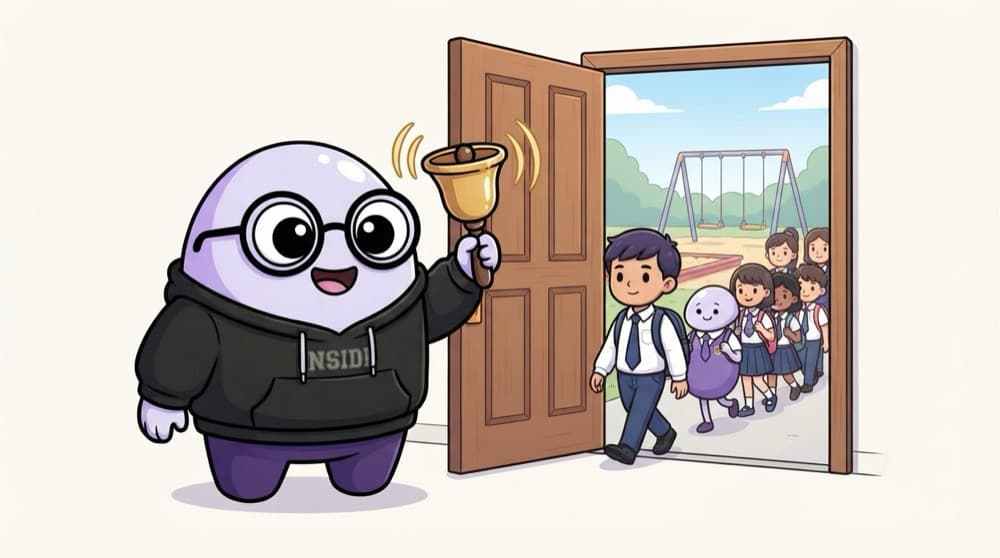
The school fire drill
Schools don't wait for a real fire to check if children know the way out. They ring the bell on a normal day and time how fast everyone reaches the ground. If one staircase jams, they fix it. Chaos experiments are fire drills for your servers.
Watch it happen
One chaos experiment
1/5Measure normal first: checkout success 99.8%, p95 latency 300 ms. This is what 'fine' looks like.
The big ideas
What you need to know
It's an experiment
You state a hypothesis and test it, like a science practical. Not random breaking for fun.
Small blast radius
Start in staging, then a tiny share of production traffic. Limit how many users could be affected.
Have an abort plan
Know how to stop the experiment instantly and what level of errors means 'stop now'.
Grow slowly
Kill one pod, then a node, then a whole zone. Each step only after the previous one passes.
See it in code
Walk through the code
1# Steady state: watch the error rate in another terminal2watch -n 2 'curl -s -o /dev/null -w "%{http_code}\n" http://shop.local/health'3 4# Inject: delete one random pod of the web deployment (staging!)5kubectl -n staging get pods -l app=web6kubectl -n staging delete pod \7 $(kubectl -n staging get pods -l app=web -o name | shuf -n 1)8 9# Observe: did Kubernetes replace it, and how fast?10kubectl -n staging get pods -l app=web -w1/3Keep a simple health check running so you see any failure the moment it happens.
Do this on a cluster you own, like kind or minikube on your laptop. Tools like Chaos Mesh and LitmusChaos automate the same idea.
Save yourself the pain
Common mistakes
Oops
Starting with a big experiment in production with no warning to anyone.
Do this instead
Begin in staging, tell the team, run during working hours and have the abort command ready.
Oops
Running chaos tests without good monitoring.
Do this instead
If you can't see the impact clearly, you learn nothing. Fix dashboards and alerts before you start breaking things.
Your mission
Your first pod-kill drill
Quick check
What should you define before injecting any failure?
Go deeper
- 1Read about Netflix's Chaos Monkey as the origin case study for this practice.
- 2Learn why testing failure handling deliberately, in a controlled way, beats discovering it during a real outage.
- 3Understand chaos engineering requires strong monitoring (Phase 11) first, to observe the effects safely.
More topics at this stop
 SRE Principles & Error Budgets
 On-Call Practices
 Postmortems & Blameless Culture
 Capacity Planning
 High Availability & Disaster Recovery
 Runbooks & Documentation
 Toil Reduction & Automation Mindset

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
