High Availability & Disaster Recovery
Part of the DevOps Roadmap
In short
High availability keeps your app running when one server dies. Disaster recovery brings it back when a whole data centre or region is gone. You need both, and they are not the same thing.
High availability minimizes downtime through redundancy (multiple servers, multiple availability zones); disaster recovery is the plan for restoring service after a major failure — related but distinct concerns.
Think of it like this
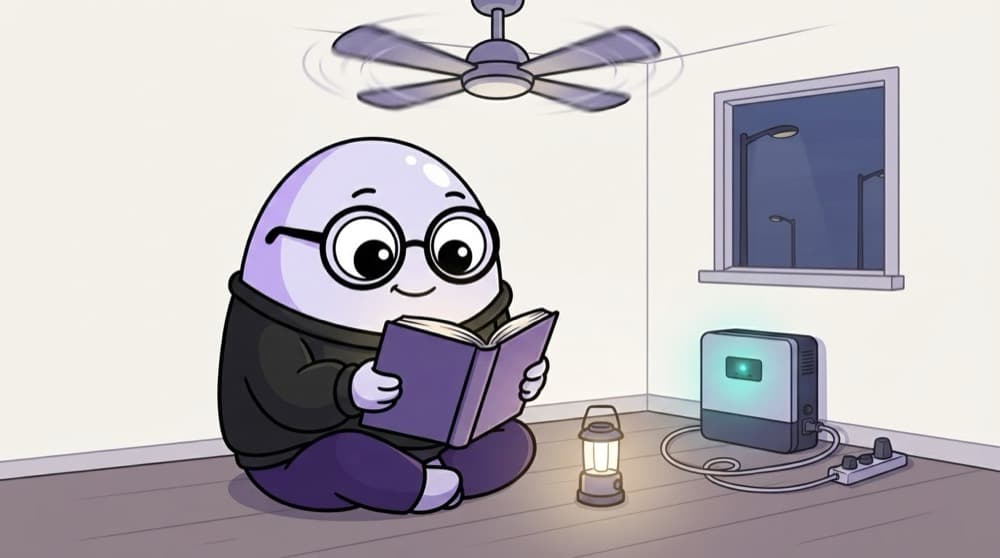
Inverter vs the spare house key
When the power cuts, the home inverter kicks in and the fan keeps spinning. You barely notice. That's high availability. If the house floods, you need your documents copied at a relative's place and a plan to move in somewhere. That's disaster recovery.
Watch it happen
Two different questions
High availability
- Survives one server or zone failing
- Automatic, seconds to failover
- Redundant copies running all the time
Disaster recovery
- Survives region loss or data deletion
- Planned, minutes to hours to restore
- Backups and a tested recovery plan
HA handles everyday failures without anyone noticing. DR is for the rare, big ones. A multi-zone setup with no backups still loses everything if someone deletes the database.
The big ideas
What you need to know
Redundancy across zones
Run at least two copies in different availability zones behind a load balancer. One zone failing then hurts nobody.
RTO: how long down
Recovery time objective is how long you can be offline after a disaster before it's unacceptable.
RPO: how much data lost
Recovery point objective is how many minutes of data you can afford to lose. Hourly backups mean up to an hour.
Test the restore
A backup you've never restored is a hope, not a plan. Practise recovery on a schedule.
How it works
A simple DR drill
- 1
Pick a scenario
For example: the production database was deleted at 14:00.
- 2
Restore
Restore the latest backup into a fresh instance, following the written runbook only.
- 3
Measure
Note how long it took (your real RTO) and the timestamp of restored data (your real RPO).
- 4
Improve
If either missed the target, change backup frequency, automation or the runbook and drill again.
See it in code
Walk through the code
1# Back up a PostgreSQL database to a file2pg_dump -Fc -h db.internal -U app shop > shop-$(date +%F-%H%M).dump3 4# Copy it to storage in a different region5aws s3 cp shop-2026-03-14-1400.dump s3://shop-backups-mumbai/ --region ap-south-16 7# Drill: restore into a fresh database and check it8createdb -h restore-test.internal -U admin shop_restore9pg_restore -h restore-test.internal -U admin -d shop_restore shop-2026-03-14-1400.dump10psql -h restore-test.internal -U admin -d shop_restore -c "select count(*) from orders;"1/3-Fc writes PostgreSQL's custom format, which pg_restore can load selectively. The date is in the name.
Managed databases offer automatic snapshots and point-in-time recovery, but the idea is the same: copies elsewhere, and a restore you've actually run.
Save yourself the pain
Common mistakes
Oops
Thinking database replicas are your backup.
Do this instead
Replicas copy deletes and bad updates instantly. You still need point-in-time backups you can roll back to.
Oops
Keeping backups in the same account and region as production.
Do this instead
Store copies in another region, ideally another account, so one mistake or breach can't wipe both.
Your mission
Back up and restore for real
Quick check
Your app runs in three availability zones, but a bad script deletes all orders. What saves you?
Go deeper
- 1Design a basic high-availability architecture with redundancy across at least 2 availability zones.
- 2Learn the difference between RTO (how fast you recover) and RPO (how much data you can afford to lose).
- 3Draft a simple disaster recovery plan for a hypothetical critical service.
More topics at this stop
 SRE Principles & Error Budgets
 On-Call Practices
 Postmortems & Blameless Culture
 Chaos Engineering Basics
 Capacity Planning
 Runbooks & Documentation
 Toil Reduction & Automation Mindset

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
