Runbooks & Documentation
Part of the DevOps Roadmap
In short
At 3am, half-asleep, nobody wants to work things out from scratch. A good runbook turns 'only Arjun knows how to fix this' into steps anyone on the team can follow.
Step-by-step guides for handling known operational tasks or incident types — turning tribal knowledge (only in one person's head) into something any on-call engineer can follow at 3am.
Think of it like this
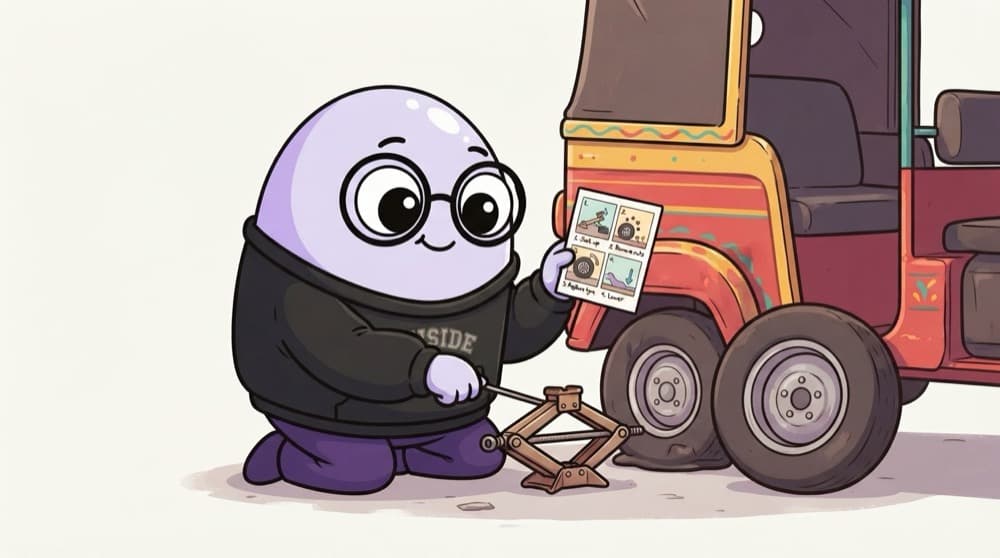
The flat-tyre card in the auto
Imagine a card taped inside an auto-rickshaw: where the jack is, which nuts to loosen first, how tight to make them. Even a new driver can change the tyre on a dark road. A runbook is that card for a known server problem.
Watch it happen
Anatomy of a good runbook
1/5Starts with which alert sends you here and what it means for users, in one or two lines.
The big ideas
What you need to know
Link it from the alert
Every page should carry a link to its runbook. Hunting for docs at 3am wastes the minutes that matter.
Exact commands
Write the real command with the real names, not 'restart the thing'. Copy-paste beats memory when tired.
Keep it fresh
Update the runbook after every incident that used it. Old steps for a renamed service are worse than none.
Automate the repeats
If a runbook is used every week, its steps should become a script or an automatic fix.
See it in code
Walk through the code
1# Runbook: Orders queue backing up2Alert: OrdersQueueDepthHigh (> 5,000 for 10 min)3Impact: Orders confirm late; customers see "processing"4 51. Check workers are running:6 kubectl -n prod get pods -l app=order-worker72. If pods are CrashLooping, read the last error:8 kubectl -n prod logs deploy/order-worker --tail=5093. If error is "DB connection refused": see runbook DB-02104. Otherwise scale up workers:11 kubectl -n prod scale deploy/order-worker --replicas=612 13Verify: queue depth falls on the Orders dashboard14Escalate after 20 min: #team-orders, then @orders-lead1/4Which alert, what threshold, what users feel. The reader knows why it matters right away.
Short, specific and in order. Someone who has never touched the orders system could follow this.
Save yourself the pain
Common mistakes
Oops
Writing one giant wiki page that explains the whole system's history.
Do this instead
Keep runbooks short and task-focused. Put background and design notes in a separate doc and link to it.
Oops
Writing runbooks once and never testing them.
Do this instead
Have a new team member follow it during a calm day. Every place they get stuck is a fix to make.
Your mission
Runbook for your own app
Quick check
Which line makes a runbook step most useful at 3am?
Go deeper
- 1Write a runbook for a common operational task (e.g. restarting a stuck service).
- 2Learn why a runbook should be specific and step-by-step, not a vague general description.
- 3Practice keeping a runbook updated as the underlying system or process changes.
More topics at this stop
 SRE Principles & Error Budgets
 On-Call Practices
 Postmortems & Blameless Culture
 Chaos Engineering Basics
 Capacity Planning
 High Availability & Disaster Recovery
 Toil Reduction & Automation Mindset

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
