Sample Size & Test Duration
Part of the Data Analyst Roadmap
In short
Run a test on 200 users and you'll mostly measure luck. Work out how many users you need before you start, and you'll know how long the test must run.
Calculating how many users (and how long) you need before a test has enough statistical power to detect a real effect — running a test too briefly is one of the most common experimentation mistakes.
Think of it like this
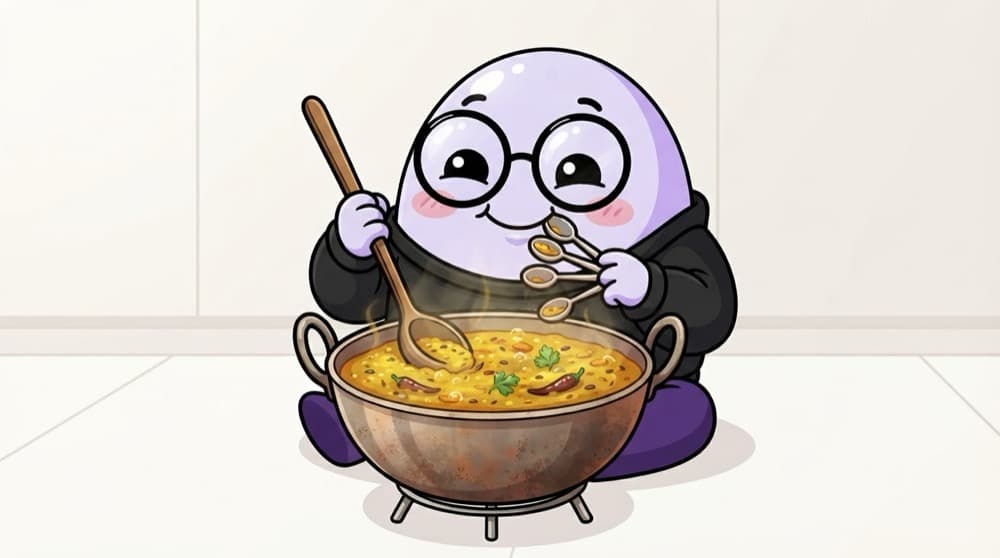
Tasting a big pot of dal
One spoon from the top of a huge pot can mislead you; maybe the salt hasn't mixed in yet. Stir and take a few spoons from different spots, and you can judge the whole pot. Bigger effects show up in fewer spoons. Subtle ones need more.
Watch it happen
Users needed per group, 10% baseline
1/5Baseline checkout rate is 10%. Each cell is the lift you want to detect and the users needed per group.
The big ideas
What you need to know
Minimum detectable effect
The smallest lift worth caring about. Pick it from business value, not hope.
Power
Chance the test detects a real effect of that size. 80% is a common choice.
Significance level
The false alarm rate you accept, usually 5%. Lower means you need more users.
Run full weeks
Weekday and weekend users behave differently. Run whole weeks, even if you hit the sample early.
See it in code
Walk through the code
1from statsmodels.stats.power import NormalIndPower2from statsmodels.stats.proportion import proportion_effectsize3import math4 5baseline, target = 0.10, 0.116effect = proportion_effectsize(target, baseline)7n = NormalIndPower().solve_power(effect_size=effect, alpha=0.05, power=0.8, ratio=1)8print("per group:", math.ceil(n))9 10daily_users = 220011days = math.ceil(2 * n / daily_users)12print("days:", days, "-> run", math.ceil(days / 7), "full weeks")1/3From 10% to 11%: a 1 percentage point lift, turned into a standard effect size.
Prints roughly 14,700 users per group and 14 days, so two full weeks at this traffic. Close to the rule of thumb.
Save yourself the pain
Common mistakes
Oops
Stopping after three days because the sample size was reached on a busy weekend.
Do this instead
Run at least one full week, ideally two, so every day of the week is covered.
Oops
Picking a 0.1% lift as the target because any win would be nice.
Do this instead
Tiny effects need huge samples. Pick the smallest lift that would actually change a decision.
Your mission
Size your own test
Quick check
You want to detect half the lift you planned before. Roughly how many more users do you need?
Go deeper
- 1Use a free sample size calculator for a hypothetical test scenario.
- 2Learn how baseline conversion rate and minimum detectable effect both affect required sample size.
- 3Understand why low-traffic features are especially hard to test reliably.
More topics at this stop
 Designing an A/B Test
 Statistical Significance in A/B Tests
 Common Experimentation Pitfalls
 Multivariate Testing (Overview)
 Reading an Experiment Readout
 Segmentation in Experiments
 Communicating Experiment Results

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
