Segmentation in Experiments
Part of the Data Analyst Roadmap
In short
The overall result says +2%, but the PM asks: what about new users, or iOS? Slicing results by segment can reveal real differences or create fake ones. The trick is knowing which.
Checking whether an experiment's effect differs across user segments (new vs returning, mobile vs desktop) — a result that looks flat overall can hide a strong effect in one segment.
Think of it like this
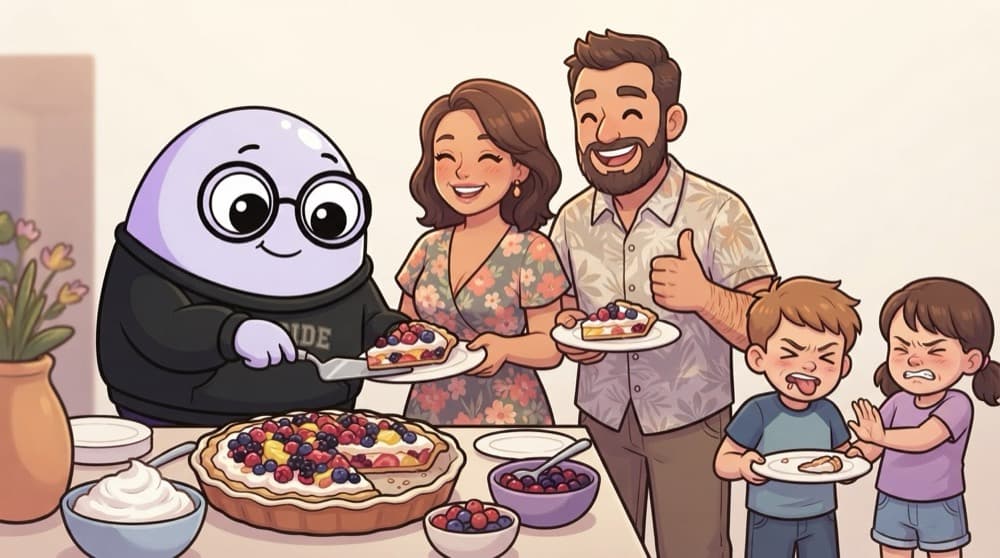
The new sweet at the family party
You bring a new sweet to a family function. Overall, people like it. But the kids make faces and the elders ask for seconds. Knowing that changes what you serve next time. Just don't slice so finely that 'left-handed cousins from Pune' becomes a finding.
Watch it happen
One result, sliced
1/5Overall, the new checkout lifts conversion by 2%. Looks like a clear win.
The big ideas
What you need to know
Plan segments upfront
Pick 2 to 4 segments with a reason, like device or new vs returning, before launch.
More slices, more flukes
Each extra segment is another chance for a random 'significant' result.
Smaller segments, wider intervals
A segment with 5% of users has much less power. Don't over-read its swings.
Surprises become new tests
An unexpected segment result is a hypothesis. Confirm it with a targeted follow-up test.
See it in code
Walk through the code
1seg = (2 results.groupby(["device", "group"])3 .agg(users=("user_id", "nunique"), conv=("converted", "sum"))4 .assign(rate=lambda d: d["conv"] / d["users"])5 .reset_index()6)7 8table = seg.pivot(index="device", columns="group", values="rate")9table["rel_lift"] = table["B"] / table["A"] - 110print(table.round(4))11print(seg.groupby("device")["users"].sum())1/3Users, conversions and rate for every device and test group.
Conversion rate per device and group, plus relative lift. Always print segment sizes alongside the lifts.
Save yourself the pain
Common mistakes
Oops
Finding one positive segment out of 25 and shipping only to them.
Do this instead
Label it exploratory and run a new test targeted at that segment to confirm.
Oops
Ignoring segment size when a tiny group shows +30%.
Do this instead
Check users and intervals. Small segments swing wildly by chance.
Your mission
Slice responsibly
Quick check
After a test, you check 20 segments and one shows p = 0.04. What's the right move?
Go deeper
- 1Break down a hypothetical test result by 2-3 plausible segments.
- 2Learn why segment-level findings need larger samples to be trustworthy (multiple comparisons).
- 3Practice deciding which segment cuts are worth checking before you run the test, not after.
More topics at this stop
 Designing an A/B Test
 Sample Size & Test Duration
 Statistical Significance in A/B Tests
 Common Experimentation Pitfalls
 Multivariate Testing (Overview)
 Reading an Experiment Readout
 Communicating Experiment Results

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
