In short
The simplest way to turn text into numbers is to count words. Add one clever tweak, TF-IDF, and you get a baseline that's still hard to beat for spam and topic classification.
Classic text representation methods — Bag of Words counts word occurrences, TF-IDF weights words by how distinctive they are to a document versus the whole corpus — simple, fast, and still useful baselines.
Think of it like this
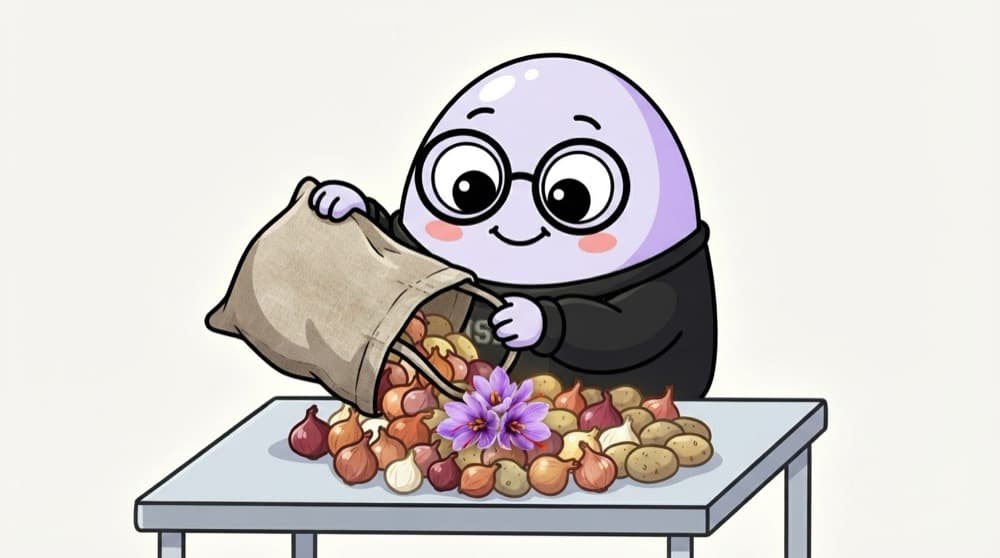
Emptying the sabzi bag
Tip a shopping bag on the table and count: 4 onions, 3 potatoes, 1 bunch of saffron. You've lost the order things went in, but the counts still tell a story. Onions are in every bag, so they say little. Saffron is rare, so it hints you're making biryani.
Watch it happen
One review's words, counted then weighted
1/4Vocabulary from a small set of reviews. Each review becomes a row of numbers over these words.
The big ideas
What you need to know
Order is lost
'Dog bites man' and 'man bites dog' get the same counts. N-grams like 'not good' bring back a little order.
TF times IDF
Term frequency rewards words used often in this document. Inverse document frequency penalises words common everywhere.
Sparse and wide
Vocabularies run to tens of thousands of columns, mostly zeros. scikit-learn stores them as sparse matrices.
A strong baseline
TF-IDF plus logistic regression trains in seconds. Beat it before reaching for big models.
See it in code
Walk through the code
1from sklearn.feature_extraction.text import CountVectorizer, TfidfVectorizer2 3docs = ["the food was great",4 "the food was cold",5 "the saffron rice was great"]6 7bow = CountVectorizer().fit(docs)8print(bow.get_feature_names_out())9print(bow.transform(docs).toarray())10 11tfidf = TfidfVectorizer().fit(docs)12print(tfidf.transform(docs).toarray().round(2))1/3Three short documents. 'the' and 'was' appear in all three.
Three tiny reviews. In the TF-IDF output, 'the' and 'was' get low weights because every review has them.
Save yourself the pain
Common mistakes
Oops
Fitting the vectorizer on all data, test set included.
Do this instead
Fit on training text only, inside a Pipeline, then transform the test text.
Oops
Using only single words for sentiment, so 'not good' looks positive.
Do this instead
Add ngram_range=(1, 2) so pairs like 'not good' become their own features.
Your mission
Spam filter in 20 lines
Quick check
Why does TF-IDF give a low weight to words like 'the'?
Go deeper
- 1Build a Bag of Words representation for a small set of sample documents.
- 2Compute TF-IDF scores and identify the most 'distinctive' words per document.
- 3Learn why TF-IDF often outperforms raw word counts for text classification.
More topics at this stop
 Text Preprocessing (Tokenization, Stemming, Lemmatization)
 Word Embeddings (Word2Vec, GloVe)
 Sequence Models for NLP
 Transformers & Attention (Overview)
 Pretrained LLMs & Fine-Tuning Basics
 Prompt Engineering for Data Tasks

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
