Word Embeddings (Word2Vec, GloVe)
Part of the Data Science Roadmap
In short
In bag of words, 'tasty' and 'delicious' are as unrelated as 'tasty' and 'tractor'. Embeddings fix that by giving each word a list of numbers where similar words sit close together.
Representing words as dense numeric vectors that capture semantic meaning — words with similar meanings end up close together in vector space, a major step up from Bag of Words' sparse counts.
Think of it like this
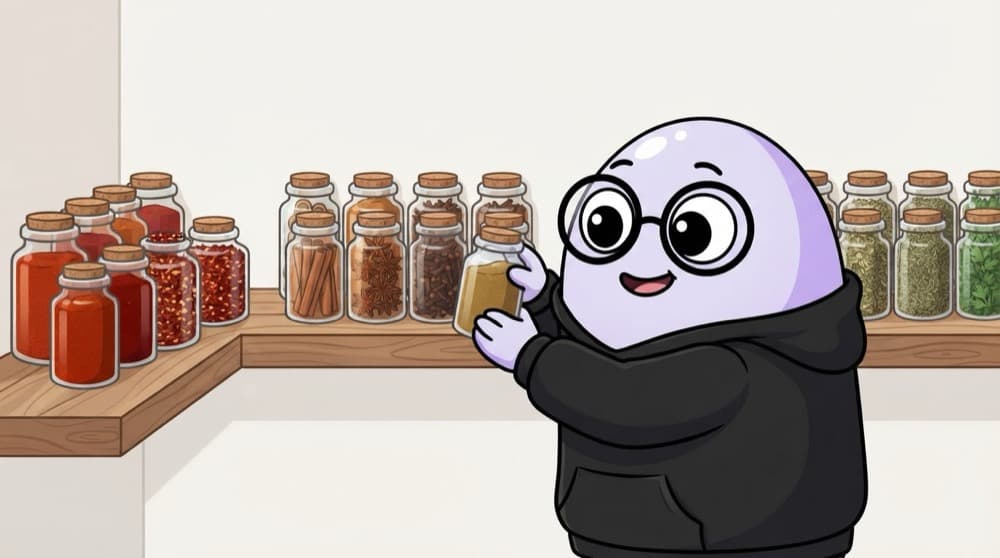
The well-organised spice shelf
A good cook arranges spices so similar ones sit together: chilli powders in one corner, green herbs in another, warm garam masala spices in the middle. You can find a substitute just by looking next door. Embeddings place words on a shelf like that, in hundreds of dimensions.
Watch it happen
How Word2Vec learns its vectors
1/5Start with lots of sentences and give every word a random vector, say 100 numbers.
The big ideas
What you need to know
Similarity is distance
Cosine similarity between two vectors measures how alike two words are used.
Vector arithmetic
The famous example: king minus man plus woman lands near queen. It works for some relations, not all.
GloVe is pretrained
GloVe vectors were trained on large public text corpora. You can download and use them directly.
One vector per word
'Bank' gets one vector for river bank and money bank. Transformers later fixed this with context-aware vectors.
See it in code
Walk through the code
1from gensim.models import Word2Vec2 3sentences = [4 ["chai", "with", "ginger", "and", "sugar"],5 ["coffee", "with", "milk", "and", "sugar"],6 ["chai", "with", "milk", "and", "cardamom"],7 ["coffee", "with", "ginger", "and", "milk"],8]9model = Word2Vec(sentences, vector_size=20, window=2, min_count=1, epochs=200, seed=1)10 11print(model.wv["chai"][:5]) # first 5 of 20 numbers12print(model.wv.most_similar("chai", topn=2))1/3Each sentence is already a list of tokens.
A toy corpus, so results are noisy. Real embeddings train on millions of sentences. Install with pip install gensim.
Save yourself the pain
Common mistakes
Oops
Training Word2Vec on a few hundred sentences and trusting the neighbours.
Do this instead
Use pretrained vectors such as GloVe for small datasets. Training your own needs a large corpus.
Oops
Expecting one embedding to separate every meaning of a word.
Do this instead
Static embeddings mix senses. Use a transformer model when context changes the meaning.
Your mission
Explore pretrained GloVe
Quick check
Why do 'tasty' and 'delicious' end up with similar Word2Vec vectors?
Go deeper
- 1Load pretrained word embeddings and explore nearest-neighbor words for a few examples.
- 2Try the classic 'king - man + woman ≈ queen' vector arithmetic example.
- 3Learn why embeddings capture semantic relationships that raw word counts can't.
More topics at this stop
 Text Preprocessing (Tokenization, Stemming, Lemmatization)
 Bag of Words & TF-IDF
 Sequence Models for NLP
 Transformers & Attention (Overview)
 Pretrained LLMs & Fine-Tuning Basics
 Prompt Engineering for Data Tasks

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
