Pretrained LLMs & Fine-Tuning Basics
Part of the Data Science Roadmap
In short
Training a large language model from scratch costs a fortune. Almost everyone starts from a pretrained model and adapts it with prompts or a little fine-tuning.
Using an already-trained large language model (via an API or open weights) and adapting it to a specific task — often via fine-tuning or, more commonly today, careful prompting.
Think of it like this
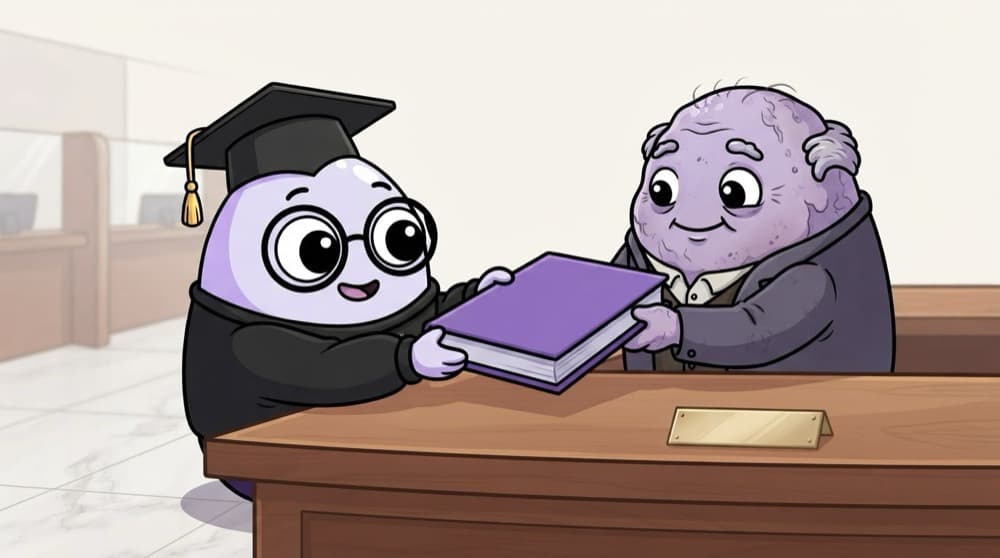
The fresh graduate's induction
A fresh graduate joins a bank. They already read, write and reason well from years of study. The bank doesn't reteach English. It runs a two-week induction on its own forms and rules. Pretraining is the degree. Fine-tuning is the induction.
Watch it happen
From general model to your task
1/5A company trained the model on huge amounts of text to predict the next token. That's pretraining.
The big ideas
What you need to know
Pretraining is general
The model learns grammar, facts and patterns from a vast text collection. It's expensive and done once.
Fine-tuning is narrow
A smaller dataset teaches a style, format or label set, such as classifying support tickets.
LoRA keeps it cheap
Instead of updating billions of weights, LoRA trains small extra matrices. It fits on much smaller GPUs.
Facts go stale
Fine-tuning is poor at adding fresh knowledge. For changing facts, retrieval from your documents usually works better.
See it in code
Walk through the code
1from datasets import load_dataset2from transformers import (AutoModelForSequenceClassification, AutoTokenizer,3 Trainer, TrainingArguments)4 5name = "distilbert-base-uncased"6tok = AutoTokenizer.from_pretrained(name)7model = AutoModelForSequenceClassification.from_pretrained(name, num_labels=2)8 9data = load_dataset("imdb")10data = data.map(lambda b: tok(b["text"], truncation=True), batched=True)11 12args = TrainingArguments("out", num_train_epochs=1, per_device_train_batch_size=16)13trainer = Trainer(model=model, args=args, processing_class=tok,14 train_dataset=data["train"].shuffle(seed=0).select(range(2000)),15 eval_dataset=data["test"].shuffle(seed=0).select(range(500)))16trainer.train()1/4Load a small pretrained model and add a new 2-label classification head.
Fine-tuning a small pretrained model for movie-review sentiment with Hugging Face. Run it on a free Colab GPU.
Save yourself the pain
Common mistakes
Oops
Jumping to fine-tuning before trying good prompts.
Do this instead
Prompt first and measure. Fine-tune only when prompts can't hit the quality, cost or speed you need.
Oops
Fine-tuning on a few dozen messy examples and expecting magic.
Do this instead
Clean, consistent, varied examples matter more than quantity. Hold some out to test.
Your mission
Zero-shot vs fine-tuned
Quick check
Your support bot needs this week's new policy details. What usually works better than fine-tuning?
Go deeper
- 1Use a pretrained model (via Hugging Face or an API) for a simple text classification task.
- 2Learn the difference between full fine-tuning, parameter-efficient fine-tuning, and prompting.
- 3Understand why fine-tuning from scratch is rarely necessary for most practical tasks today.
More topics at this stop
 Text Preprocessing (Tokenization, Stemming, Lemmatization)
 Bag of Words & TF-IDF
 Word Embeddings (Word2Vec, GloVe)
 Sequence Models for NLP
 Transformers & Attention (Overview)
 Prompt Engineering for Data Tasks

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
