Transformers & Attention (Overview)
Part of the Data Science Roadmap
In short
ChatGPT, Claude, BERT and modern translation all run on transformers. Their key trick, attention, lets every word look at every other word at once instead of reading one by one.
The architecture behind virtually all modern NLP and LLMs — the attention mechanism lets a model weigh the relevance of every other word when processing each word, capturing context far better than RNNs.
Think of it like this
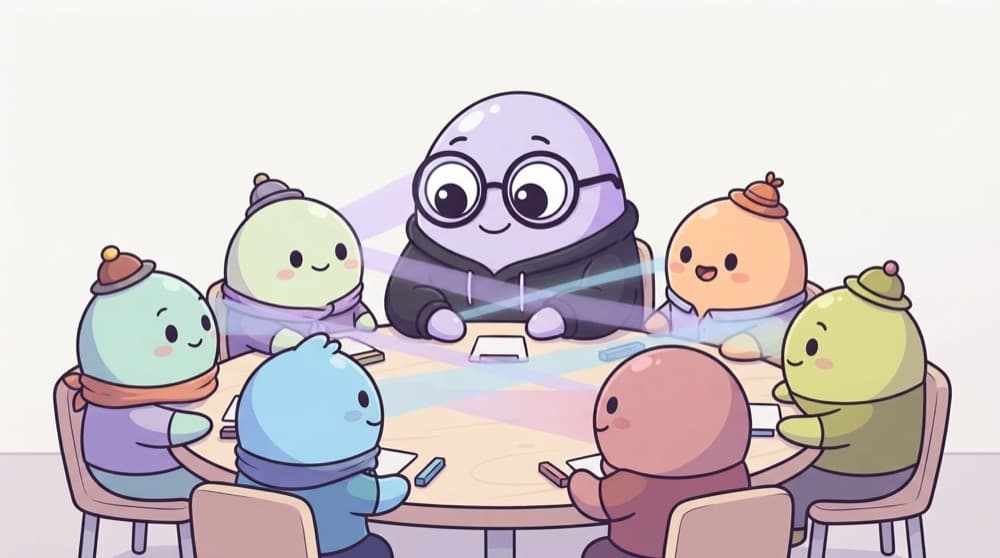
The group discussion table
In a group discussion, everyone hears everyone at the same time. When Riya says 'it', you glance at whoever mentioned the laptop to know what 'it' means. You pay more attention to some people and less to others. That's self-attention.
Watch it happen
Working out what 'it' means
1/5Sentence: 'The cat sat on the mat because it was tired.' The token 'it' builds a query vector.
The big ideas
What you need to know
Query, key, value
Each token makes three vectors. Query asks, key advertises, value is what gets passed on.
All at once
No word-by-word loop, so training runs in parallel on GPUs. That's a big reason transformers scaled up.
Many heads, many layers
Multiple attention heads catch different relations. Dozens of stacked layers build deep understanding.
Position added in
Attention alone ignores order, so a positional encoding is added to tell the model where each token is.
See it in code
Walk through the code
1import numpy as np2 3def softmax(x):4 e = np.exp(x - x.max(axis=-1, keepdims=True))5 return e / e.sum(axis=-1, keepdims=True)6 7Q = np.random.rand(4, 8) # 4 tokens, 8-dim queries8K = np.random.rand(4, 8) # keys9V = np.random.rand(4, 8) # values10 11weights = softmax(Q @ K.T / np.sqrt(8)) # how much each token attends to each other12out = weights @ V # blend of values13print(weights.round(2))1/4A stable softmax: each row becomes weights that add up to 1.
Scaled dot-product attention, the heart of a transformer. Real models learn Q, K and V from the input.
Save yourself the pain
Common mistakes
Oops
Thinking attention weights fully explain why a model made a decision.
Do this instead
They give hints, not proof. Use proper explanation tools before drawing strong conclusions.
Oops
Assuming transformers have unlimited memory of a document.
Do this instead
Every model has a context window limit in tokens. Long documents must be chunked or summarised.
Your mission
See attention in action
Quick check
What advantage does self-attention have over an RNN?
Go deeper
- 1Read a beginner-friendly visual explainer of the attention mechanism.
- 2Learn why Transformers can be trained in parallel, unlike sequential RNNs.
- 3Understand this architecture is the foundation for models like BERT and GPT.
More topics at this stop
 Text Preprocessing (Tokenization, Stemming, Lemmatization)
 Bag of Words & TF-IDF
 Word Embeddings (Word2Vec, GloVe)
 Sequence Models for NLP
 Pretrained LLMs & Fine-Tuning Basics
 Prompt Engineering for Data Tasks

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
