In short
If your phone buzzes twenty times a night for things that fix themselves, you'll start ignoring it and miss the alert that mattered. Good alerting means fewer, better alerts.
Alerts should be actionable, not noisy — every alert that fires should require a real human response, or it trains the team to ignore alerts entirely (alert fatigue).
Think of it like this
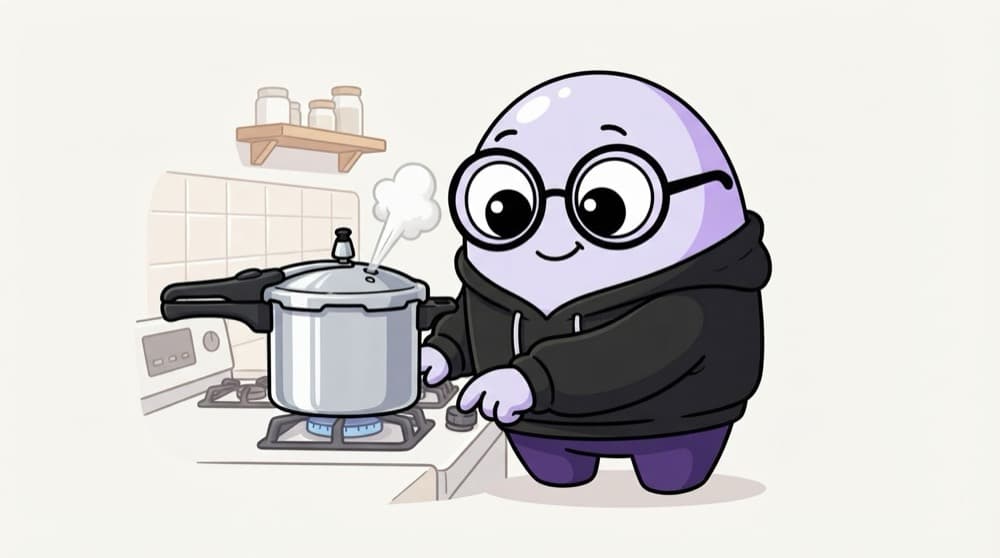
The pressure cooker whistle
A pressure cooker whistles when there's a real reason to act: the dal is ready, turn off the gas. Imagine one that whistled every minute; you'd stop listening and the dal would burn. Every alert should be a whistle that means 'act now', or it shouldn't make a sound.
Watch it happen
Which alerts should page a human?
1/5Six candidate alerts. The test: does a user feel it, or will they soon, and must someone act now?
The big ideas
What you need to know
Alert on symptoms
Page on what users feel (errors, latency, downtime). Use causes like CPU for dashboards and debugging.
Every page needs an action
If the response is 'wait and see', it isn't a page. Make it a ticket or remove it.
Use a 'for' duration
Require the condition to hold for several minutes, so short blips don't wake anyone.
Link a runbook
Every alert should say what it means, how bad it is and the first steps to take.
See it in code
Walk through the code
1groups:2 - name: shop3 rules:4 - alert: HighErrorRate5 expr: |6 sum(rate(http_requests_total{app="shop", status=~"5.."}[5m]))7 / sum(rate(http_requests_total{app="shop"}[5m])) > 0.028 for: 10m9 labels: { severity: page }10 annotations:11 summary: "Shop 5xx above 2% for 10 minutes"12 runbook_url: "https://wiki.example.com/runbooks/shop-5xx"1/4One alert in a rule group, named after the symptom, not the cause.
A Prometheus alerting rule. Alertmanager then routes severity: page to the on-call phone and lower severities to chat or tickets.
Save yourself the pain
Common mistakes
Oops
Paging on CPU above 80% on every server.
Do this instead
High CPU with happy users is fine. Page on user-facing symptoms and keep CPU on the dashboard.
Oops
Letting an alert fire every night and muting it 'for now'.
Do this instead
Fix it, tune it or delete it this week. A muted alert is a trap for the next on-call engineer.
Your mission
Audit an alert list
Quick check
Which of these is the best candidate for waking someone at 3 am?
Go deeper
- 1Audit a hypothetical alert rule and decide if it's genuinely actionable or just noise.
- 2Learn the concept of alert fatigue and why over-alerting is more dangerous than under-alerting.
- 3Practice writing an alert with a clear runbook link explaining what to do when it fires.
More topics at this stop
 Monitoring vs Observability
 Metrics, Logs & Traces (The 3 Pillars)
 Prometheus Fundamentals
 Grafana Dashboards
 The ELK / EFK Stack
 Distributed Tracing (Jaeger, OpenTelemetry)
 SLIs, SLOs & Error Budgets
 Incident Response Basics

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
