Monitoring vs Observability
Part of the DevOps Roadmap
In short
Your dashboard is all green, yet users say checkout is slow for some of them. Monitoring tells you when known things break. Observability lets you work out why something you never predicted is going wrong.
Monitoring tracks known metrics against known thresholds ('is CPU above 80%?'); observability is the broader ability to ask new, unanticipated questions about system state from its outputs — you need both.
Think of it like this
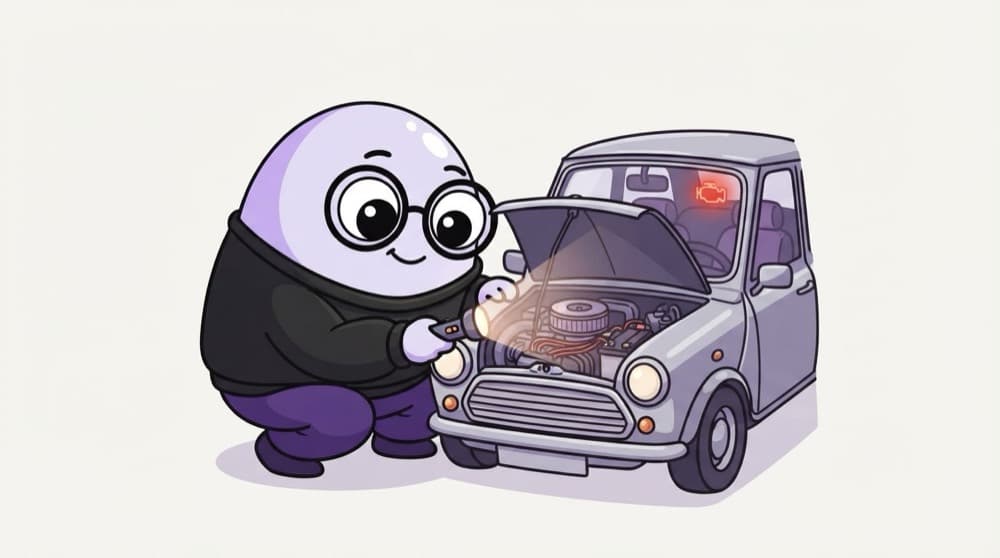
Warning lamp vs the mechanic
The car dashboard lights up for things the maker predicted: low oil, engine hot. But for a strange rattle only on bumpy roads, you need a mechanic who can open the bonnet and investigate. Monitoring is the warning lamp; observability is the mechanic's ability to dig in.
Watch it happen
Two questions, two tools
Monitoring
- Known questions: is CPU above 80%?
- Dashboards and threshold alerts
- Tells you that something broke
Observability
- New questions during an incident
- Rich metrics, logs and traces
- Helps you find out why
You need both. Monitoring wakes you up; observability gets you back to sleep by showing the cause.
The big ideas
What you need to know
Monitoring watches knowns
You decide in advance what to measure and when to alert. Great for familiar failure modes.
Observability explores unknowns
If your telemetry is rich enough, you can slice it by any field during an incident, like customer, region or version.
Context is everything
Metrics and logs tagged with service, version and request ID turn guesses into answers.
Built from signals
Observability rests on metrics, logs and traces, ideally linked to each other.
See it in code
Walk through the code
1# Monitoring: a known question, asked every minute2avg(rate(node_cpu_seconds_total{mode!="idle"}[5m])) > 0.83 4# Observability: a new question you thought of during an incident5histogram_quantile(0.99,6 sum by (le, route) (rate(http_request_duration_seconds_bucket{app="shop"}[5m])))1/2A fixed check: is average CPU busy time above 80%? Perfect for an alert rule.
Both are PromQL queries for Prometheus. The second only works if your app exports a latency histogram with a route label.
Save yourself the pain
Common mistakes
Oops
Adding more and more dashboards and calling the system observable.
Do this instead
Dashboards answer old questions. Invest in labelled metrics, structured logs and traces so you can ask new ones.
Oops
Thinking observability is a product you buy.
Do this instead
It's a property of your system. Tools help, but only if your code emits useful, well-labelled telemetry.
Your mission
Known vs unknown
Quick check
Users in one city report slow pages, but all your CPU and memory alerts are quiet. What helps most?
Go deeper
- 1Give one example of a monitored metric and one example of an observability-driven investigation.
- 2Learn why observability matters more as systems get more distributed and unpredictable.
- 3Understand monitoring answers known questions; observability helps you find the right question.
More topics at this stop
 Metrics, Logs & Traces (The 3 Pillars)
 Prometheus Fundamentals
 Grafana Dashboards
 The ELK / EFK Stack
 Distributed Tracing (Jaeger, OpenTelemetry)
 Alerting Best Practices
 SLIs, SLOs & Error Budgets
 Incident Response Basics

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
