Context Window Management
Part of the AI Engineer Roadmap
In short
Your RAG app retrieves 12 good chunks, the user has a long chat history, and the system prompt is big. They won't all fit, and cramming hurts answers anyway. Context management decides what goes in.
Deciding what retrieved content actually fits in the model's context window and in what order — critical once your knowledge base is larger than what any single prompt can hold.
Think of it like this
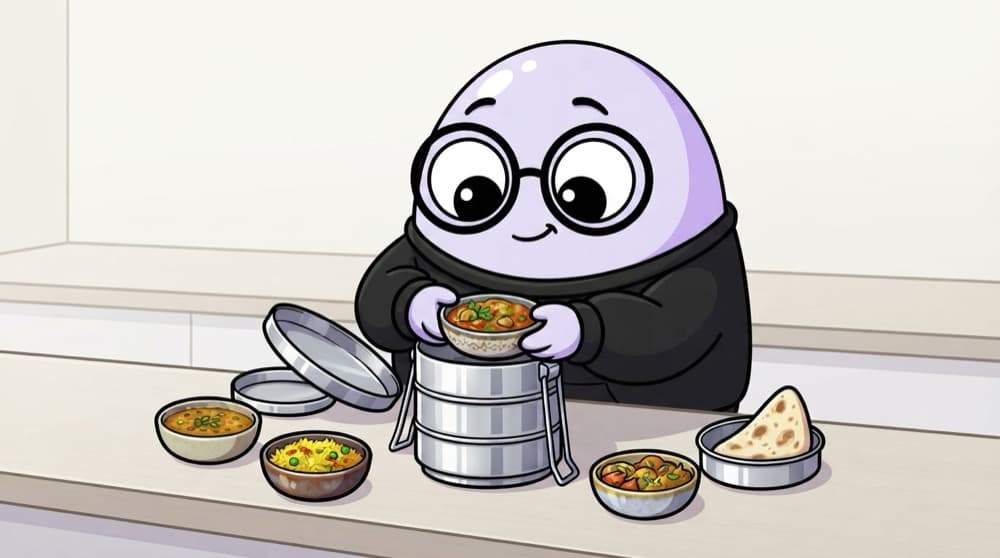
Packing the three-tier tiffin
Amma made six dishes, but the tiffin has three compartments. She packs the dal, sabzi and rotis you'll actually eat, and leaves the rest. Your prompt is the tiffin: fixed space, so pack the most useful pieces and leave the rest at home.
Watch it happen
Splitting an 8,000-token budget (illustrative)
1/5Toy budget: 8,000 tokens for everything, input and output together.
The big ideas
What you need to know
Budget in tokens
Count tokens with the model's tokenizer. Reserve the reply space first, then fill the rest by priority.
Best chunks first
After reranking, add chunks in order of relevance and stop when the budget is used.
Summarise old history
Replace older chat turns with a short summary so the conversation keeps its thread without the bulk.
Position matters
Models can overlook details buried mid-prompt. Put the most relevant chunk near the start or end.
See it in code
Walk through the code
1import tiktoken2enc = tiktoken.get_encoding("cl100k_base")3n = lambda s: len(enc.encode(s))4 5def pack(system, question, ranked_chunks, limit=8000, reply=1000):6 budget = limit - reply - n(system) - n(question)7 picked = []8 for chunk in ranked_chunks: # already sorted best-first9 if n(chunk) > budget:10 continue11 picked.append(chunk)12 budget -= n(chunk)13 return picked1/3A tokenizer-based counter. Character counts are not reliable enough.
Greedy packing: reserve space, then add the best chunks that still fit. Swap in your model's own tokenizer.
Save yourself the pain
Common mistakes
Oops
Filling the window to the limit because the model allows it.
Do this instead
More text means more cost, slower replies and more noise. Send only what helps.
Oops
Silently dropping the system prompt when the chat gets long.
Do this instead
Always keep the system prompt. Trim or summarise history first.
Your mission
Pack under pressure
Quick check
Your RAG prompt plus history exceeds the model's limit. What should you trim first?
Go deeper
- 1Practice truncating and prioritizing retrieved chunks to fit a token budget.
- 2Learn how chunk ordering within the prompt affects model attention.
- 3Test what happens to answer quality as you push closer to the context limit.
More topics at this stop
 Embeddings & Semantic Search
 Vector Databases (Pinecone, Chroma, Weaviate, FAISS)
 Chunking Strategies
 RAG Architecture
 Hybrid Search (Keyword + Vector)
 Reranking
 Evaluating RAG Pipelines
 Knowledge Graphs (Overview)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
