Embeddings & Semantic Search
Part of the AI Engineer Roadmap
In short
Search 'cheap phone with good camera' and keyword search misses 'budget smartphones for photography'. Embeddings turn text into numbers that capture meaning, so search finds what you meant, not just what you typed.
Converting text into dense vectors where semantic similarity maps to vector distance — the mechanism that lets you search 'by meaning' instead of exact keyword match.
Think of it like this
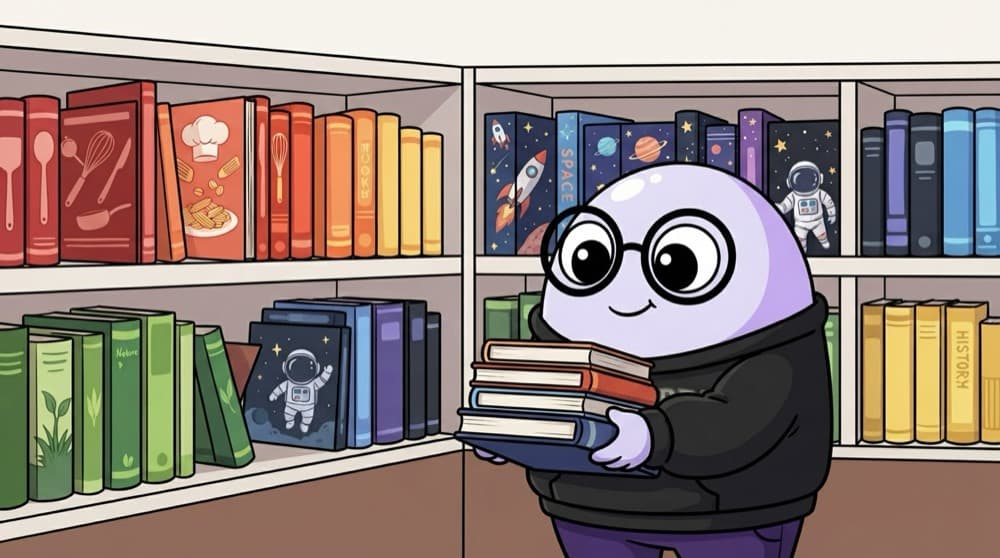
The librarian who shelves by meaning
A good librarian doesn't shelve books alphabetically. Cookbooks sit together, space books sit together, and a book on Indian street food ends up near both cooking and travel. Embeddings place text in a 'meaning space' the same way: similar ideas end up close together.
Watch it happen
Scoring documents against one query
1/5Query: 'affordable smartphone'. Each document has already been turned into an embedding vector.
The big ideas
What you need to know
Text becomes a vector
An embedding model maps text to a list of numbers, often a few hundred to a few thousand long.
Closeness = similarity
Cosine similarity measures the angle between two vectors. Similar meanings point in similar directions.
Same model for both
Documents and queries must be embedded by the same model. Vectors from different models can't be compared.
Pick for your language
Some embedding models handle Hindi and other Indian languages much better. Test with your real queries.
See it in code
Walk through the code
1# pip install sentence-transformers2from sentence_transformers import SentenceTransformer, util3 4model = SentenceTransformer("all-MiniLM-L6-v2")5 6docs = ["Best budget phones under Rs 15,000", "Tips for night photography",7 "India vs Australia live score", "Cheap mobiles with long battery life"]8doc_vecs = model.encode(docs)9query_vec = model.encode("affordable smartphone")10 11scores = util.cos_sim(query_vec, doc_vecs)[0]12for doc, s in sorted(zip(docs, scores), key=lambda x: -x[1]):13 print(round(float(s), 2), doc)1/3Load a small English embedding model. It downloads once.
A small, free embedding model that runs on a laptop. Notice how phone-related docs rank highest.
Save yourself the pain
Common mistakes
Oops
Assuming semantic search beats keyword search for everything.
Do this instead
Exact codes, names and IDs like 'CS301' often match better with keywords. Many systems combine both.
Oops
Switching embedding models without re-embedding your documents.
Do this instead
New model, new vector space. Re-embed everything when you change models.
Your mission
Search your notes by meaning
Quick check
Why must queries and documents use the same embedding model?
Go deeper
- 1Generate embeddings for a set of documents and compute cosine similarity between them.
- 2Build a simple semantic search over a small document collection.
- 3Compare embedding-based search results to keyword search on the same queries.
More topics at this stop
 Vector Databases (Pinecone, Chroma, Weaviate, FAISS)
 Chunking Strategies
 RAG Architecture
 Hybrid Search (Keyword + Vector)
 Reranking
 Context Window Management
 Evaluating RAG Pipelines
 Knowledge Graphs (Overview)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
