Evaluating RAG Pipelines
Part of the AI Engineer Roadmap
In short
'It seems to work' is not a test. A RAG system can fail at finding the right chunk or at using it correctly. Evaluating each part separately tells you exactly what to fix.
Measuring both retrieval quality (did we find the right chunks?) and generation quality (did the model use them correctly?) — RAG systems fail in ways generic LLM evals don't catch.
Think of it like this
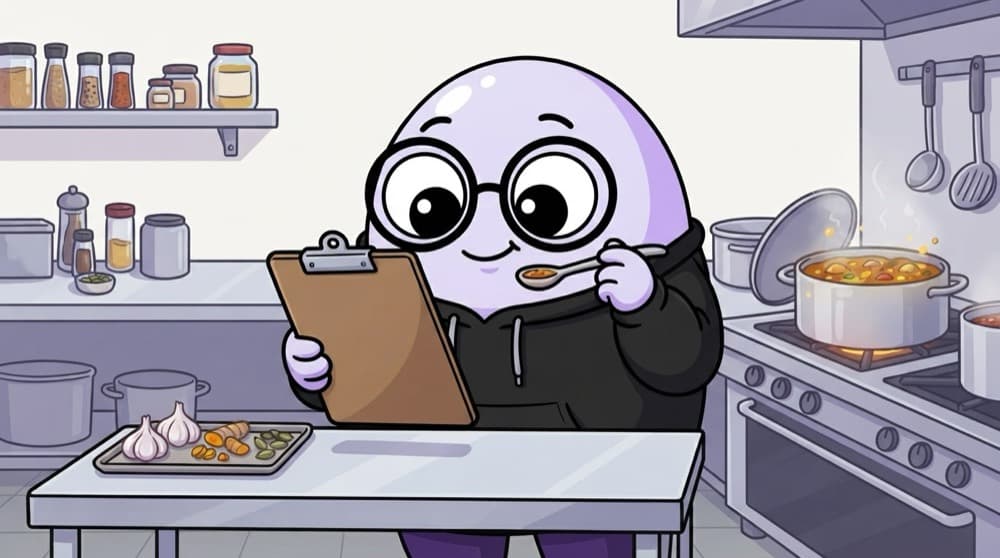
The food inspector
A food inspector doesn't only taste the curry. She also checks the raw ingredients. Bad dish, good ingredients? Blame the cooking. Bad ingredients? Blame the supplier. RAG evaluation checks retrieval (ingredients) and generation (cooking) separately.
Watch it happen
What to measure
1/5Start with 30 to 100 real questions, each with the correct answer and the chunk or page that contains it.
The big ideas
What you need to know
Build a golden set
Real user questions with known answers and source pages. It's the most valuable asset in a RAG project.
Split the blame
Low recall means fix chunking, embeddings or search. Good recall but bad answers means fix the prompt or model.
LLM judges help
Tools like Ragas use an LLM to score faithfulness and relevance. Spot-check them against your own ratings.
Re-run on every change
New chunk size, new model, new prompt? Rerun the set and compare before shipping.
See it in code
Walk through the code
1def recall_at_k(golden, search, k=5):2 hits = 03 for item in golden: # {"question": ..., "chunk_id": ...}4 ids = search(item["question"], k) # returns a list of chunk ids5 hits += item["chunk_id"] in ids6 return hits / len(golden)7 8for k in (1, 3, 5, 10):9 print(f"recall@{k}: {recall_at_k(golden_set, my_search, k):.0%}")1/3For each question, check whether its known correct chunk was retrieved.
Measure retrieval on its own first. If recall@5 is low, no prompt tweak will save the answers.
Save yourself the pain
Common mistakes
Oops
Writing test questions by copying sentences straight from the documents.
Do this instead
Real users phrase things differently. Use real or realistic questions with different wording.
Oops
Only scoring final answers.
Do this instead
Score retrieval separately, so you know which part to fix.
Your mission
Your first golden set
Quick check
Recall@5 is 95 percent, but many answers are still wrong. Where is the problem most likely?
Go deeper
- 1Build a small test set of questions with known correct answers/sources.
- 2Evaluate retrieval separately from generation to isolate where failures occur.
- 3Learn frameworks like RAGAS that formalize RAG-specific evaluation metrics.
More topics at this stop
 Embeddings & Semantic Search
 Vector Databases (Pinecone, Chroma, Weaviate, FAISS)
 Chunking Strategies
 RAG Architecture
 Hybrid Search (Keyword + Vector)
 Reranking
 Context Window Management
 Knowledge Graphs (Overview)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
