In short
"Explain overfitting." "Why L2 regularisation?" "What does cross-validation actually do?" These come up in nearly every AI interview. Clear, simple answers here earn you the interviewer's trust early.
Core interview territory — expect questions on bias-variance, regularization, evaluation metrics, and the math (linear algebra, probability) underlying common algorithms.
Think of it like this
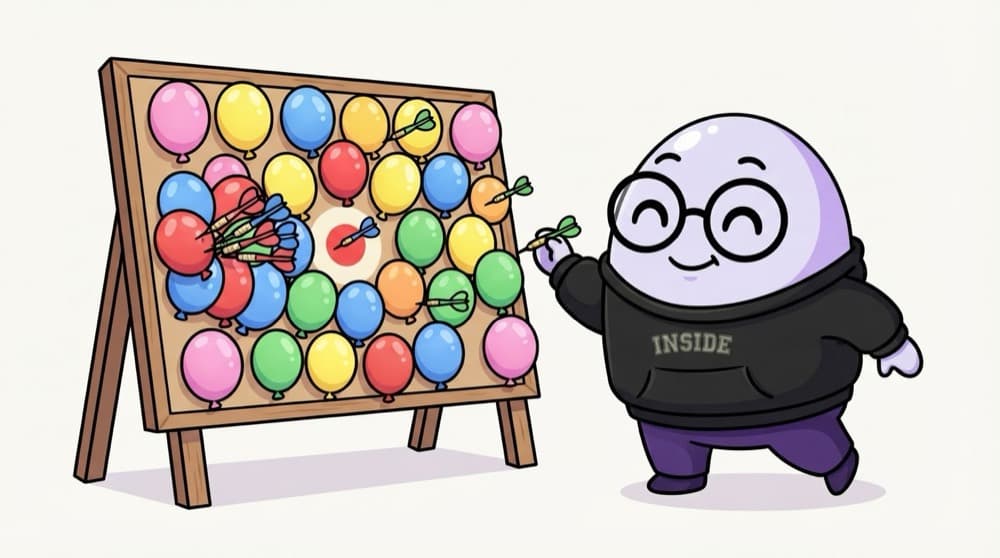
Darts at the mela balloon stall
One friend throws darts that land close together, but always a bit left of the balloon. That's high bias: consistently wrong. Another friend's darts land all over the board. That's high variance: wildly inconsistent. A good model, like a good thrower, is both on target and steady.
Watch it happen
5-fold cross-validation
1/5Split the training data into five equal folds. Each fold takes one turn as the test set.
The big ideas
What you need to know
Bias vs variance
Underfitting misses the pattern, overfitting memorises noise. Compare training and validation error to tell which.
Regularisation adds a penalty
L2 shrinks all weights a little. L1 can push some to exactly zero, which also picks features.
The math they ask
Dot products and matrices, derivatives for gradient descent, and probability basics like Bayes' rule and conditional probability.
Metrics with a reason
Know precision, recall, F1, ROC-AUC and RMSE, and when each one misleads.
How it works
Answering "What is overfitting?"
- 1
Define it plainly
The model learns noise in the training data, so it does well there and badly on new data.
- 2
Give an example
A deep decision tree scores 100% on training data but much lower on validation.
- 3
Say how you spot it
Training error low, validation error high, and the gap grows as the model gets more complex.
- 4
List fixes
More data, simpler model, regularisation, early stopping, dropout for neural nets.
See it in code
Walk through the code
1from sklearn.datasets import load_breast_cancer2from sklearn.model_selection import cross_val_score3from sklearn.tree import DecisionTreeClassifier4 5X, y = load_breast_cancer(return_X_y=True)6 7for depth in [None, 4]:8 tree = DecisionTreeClassifier(max_depth=depth, random_state=0)9 train_acc = tree.fit(X, y).score(X, y)10 cv_acc = cross_val_score(tree, X, y, cv=5).mean()11 print(f"depth={depth}: train={train_acc:.2f} cv={cv_acc:.2f}")1/3Try an unlimited-depth tree, then one capped at depth 4.
Overfitting you can see. The unlimited tree scores near-perfect on data it has seen; cross-validation shows how it does on data it hasn't.
Save yourself the pain
Common mistakes
Oops
Reciting a textbook definition with no example.
Do this instead
Pair every definition with a quick example, ideally from your own project: "In my churn model, I saw…".
Oops
Freezing when asked to derive something, like the gradient of squared error.
Do this instead
Practise 4 or 5 small derivations on paper. Talk through each step out loud even if you slip.
Your mission
Fundamentals rapid-fire
Quick check
Training error is 2% and validation error is 25%. What's the most likely problem?
Go deeper
- 1Review your Phase 2, 5 and 6 notes and be able to explain each concept without notes.
- 2Practice explaining bias-variance tradeoff and regularization out loud in under two minutes.
- 3Do a few mock questions on 'when would you use X algorithm over Y.'
More technical at this stop
 Deep Learning & Architectures
 LLM/GenAI Concepts
 System design (AI/ML)
 RAG & Vector Database Design
 Prompt Engineering Questions
 Model Evaluation & Trade-offs
 Debugging Model Performance Issues

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
