Model Evaluation & Trade-offs
Part of the AI Engineer Roadmap
In short
"Which metric would you use, and why?" Anyone can call accuracy_score. Interviewers want to see you pick the metric that matches what a mistake actually costs the business.
Interviewers probe whether you can choose the right metric for a business problem, not just compute one — expect 'what metric would you use and why' questions.
Think of it like this
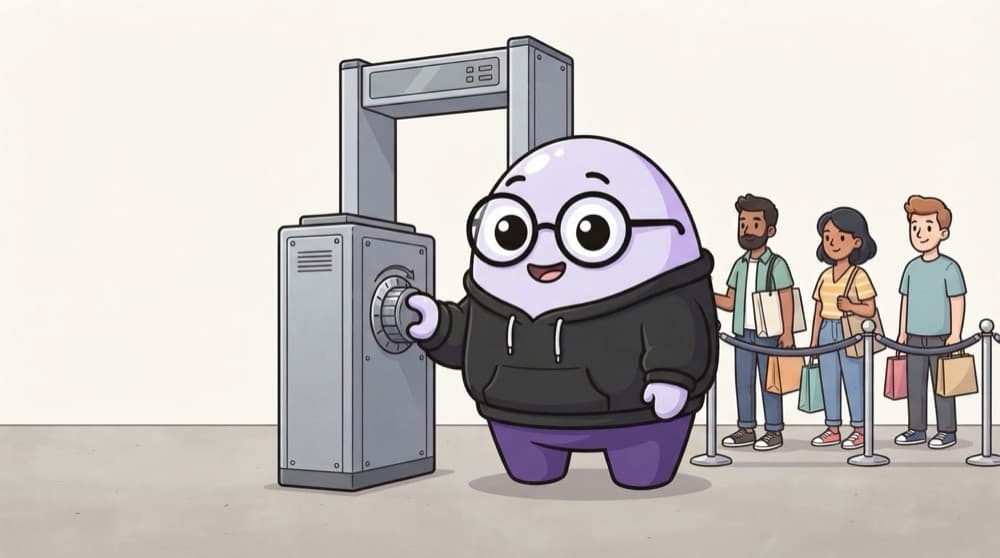
The mall metal detector
Turn the mall detector very sensitive and it beeps for every belt buckle, so the queue crawls. Turn it down and the queue flies, but something dangerous might slip through. There's no perfect setting, only the right one for what's at stake. Choosing a model threshold is the same call.
Watch it happen
Precision vs recall
Precision
- Of the flagged, how many were right?
- High when false alarms are costly
- Example: spam filter on work email
Recall
- Of the real cases, how many caught?
- High when misses are costly
- Example: cancer screening, fraud
Raising the threshold usually lifts precision and drops recall. Ask which mistake hurts more, then pick the threshold on validation data.
The big ideas
What you need to know
Start from the cost of mistakes
A missed fraud and a blocked genuine payment cost very different amounts. Let that pick the metric.
Accuracy lies on imbalanced data
With 1% positives, always guessing "no" scores 99%. Use precision, recall, F1 or PR-AUC instead.
The threshold is a choice
0.5 is just a default. Tune it on validation data to hit the business target.
Offline isn't the whole story
Latency, cost and an online A/B test matter too. A slightly worse but much faster model can win.
See it in code
Walk through the code
1from sklearn.metrics import precision_recall_curve2import numpy as np3 4# y_true: 1 = fraud, y_score: model's fraud probability on the validation set5precision, recall, thresholds = precision_recall_curve(y_true, y_score)6 7# Business rule: catch at least 90% of fraud, then keep precision as high as possible8ok = recall[:-1] >= 0.909best = np.argmax(np.where(ok, precision[:-1], -1))10print("threshold", thresholds[best], "precision", precision[best], "recall", recall[best])1/3Get precision and recall at every possible threshold on validation data.
Picking a threshold from a business rule instead of using 0.5. The precision and recall arrays have one more entry than thresholds, hence the [:-1].
Save yourself the pain
Common mistakes
Oops
Answering "I'd use accuracy" for a fraud or disease problem.
Do this instead
Point out the imbalance, then choose recall or precision based on which error is worse, and say why.
Oops
Tuning the threshold on the test set.
Do this instead
Tune on validation data and report the final number on an untouched test set.
Your mission
Pick a threshold for a rule
Quick check
A fraud model flags transactions for manual review, and missing fraud is far costlier than a review. What should you prioritise?
Go deeper
- 1Practice justifying a metric choice for several different business scenarios.
- 2Be ready to discuss precision/recall trade-offs with concrete cost implications.
- 3Prepare a story about a time a model looked good on one metric but failed in practice.
More technical at this stop
 ML Fundamentals & Math
 Deep Learning & Architectures
 LLM/GenAI Concepts
 System design (AI/ML)
 RAG & Vector Database Design
 Prompt Engineering Questions
 Debugging Model Performance Issues

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
