Backpropagation & Gradient Descent
Part of the Data Science Roadmap
In short
A new network makes terrible guesses. Backpropagation works out which weights caused the error, and gradient descent nudges them the right way. Repeat a few thousand times and the guesses get good.
The algorithm that computes how much each weight contributed to the error, then adjusts weights to reduce it — the mechanism by which a neural network actually learns from data.
Think of it like this
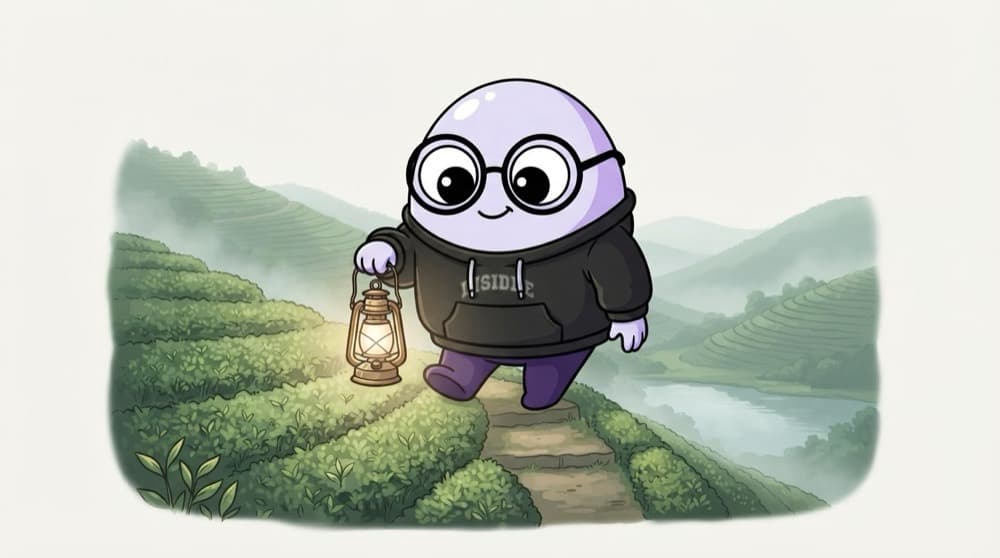
Walking down a foggy hill
You're on a misty tea-garden hill in Munnar and want to reach the valley. You can't see far, but you can feel which way the ground slopes under your feet. Take a small step downhill, feel again, step again. The step size is your learning rate.
Watch it happen
One training step
1/5Push a batch of examples through the network to get predictions.
The big ideas
What you need to know
Gradient points uphill
The gradient shows the direction where the loss grows fastest. You step the opposite way.
Learning rate matters
Too big and you overshoot the valley and bounce around. Too small and training crawls.
Chain rule does the work
Backprop passes error backwards layer by layer, reusing results so all gradients come out in one sweep.
Mini-batches
Updating on small batches of 32 to 256 rows is faster and adds helpful noise. That's stochastic gradient descent.
See it in code
Walk through the code
1import numpy as np2 3x = np.array([1.0, 2.0, 3.0, 4.0])4y = np.array([2.0, 4.0, 6.0, 8.0]) # true rule: y = 2x5w, lr = 0.0, 0.056 7for step in range(20):8 pred = w * x # forward pass9 loss = ((pred - y) ** 2).mean() # mean squared error10 grad = (2 * (pred - y) * x).mean() # d(loss)/dw11 w -= lr * grad # step downhill12print(round(w, 3)) # close to 2.01/4Start with a wrong weight of 0 and a learning rate of 0.05.
Gradient descent with one weight, by hand. Frameworks compute grad for millions of weights automatically.
Save yourself the pain
Common mistakes
Oops
Raising the learning rate to train faster and ignoring a loss that jumps around.
Do this instead
If loss explodes or zigzags, lower the learning rate. Try values like 1e-2, 1e-3 and 1e-4.
Oops
Judging training only by training loss going down.
Do this instead
Track validation loss too. If it rises while training loss falls, the model is overfitting.
Your mission
Break the learning rate
Quick check
What does backpropagation calculate?
Go deeper
- 1Read a conceptual (not fully mathematical) walkthrough of backpropagation.
- 2Connect this back to Phase 2's gradient descent — backprop just computes the gradients efficiently.
- 3Train a tiny network and watch the loss decrease over training epochs.
More topics at this stop
 Neural Network Basics
 Activation Functions
 Building Networks With TensorFlow / Keras
 Building Networks With PyTorch
 Convolutional Neural Networks (CNNs)
 Recurrent Neural Networks (RNNs) & LSTMs
 Transfer Learning
 Regularization in Deep Learning (Dropout, Batch Norm)
 GPUs & Training Basics

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
