
Regularization in Deep Learning (Dropout, Batch Norm)
Part of the Data Science Roadmap
In short
Deep networks are so powerful they can memorise the training set, labels and noise included. Dropout and batch norm help them generalise instead, and train more smoothly.
Techniques specific to neural networks that reduce overfitting — dropout randomly disables neurons during training, batch normalization stabilizes and speeds up training by normalizing layer inputs.
Think of it like this
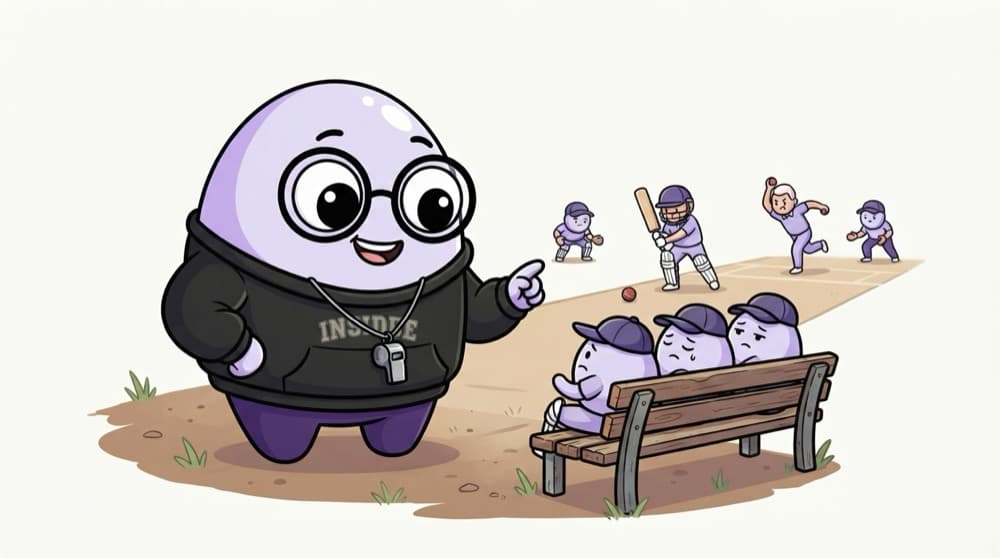
Random rest days at nets practice
A coach rests random players at each nets session. Nobody can rely on the star batter always being there, so everyone learns to contribute. On match day the whole team plays. That's dropout: random neurons sit out in training, and all play at prediction time.
Watch it happen
Dropout with p = 0.3 on six neurons
1/5A hidden layer with six neurons. During training, each batch drops about 30% of them at random.
The big ideas
What you need to know
Dropout breaks reliance
Neurons can't depend on one partner, so they learn more independent, useful features.
Batch norm steadies
BatchNorm rescales each layer's outputs within a batch. Training gets more stable and can use higher learning rates.
Train vs eval mode
Both layers behave differently in training and prediction. Always switch modes correctly.
Early stopping too
Stop training when validation loss stops improving. Weight decay, an L2 penalty, also helps.
See it in code
Walk through the code
1import torch2from torch import nn3 4model = nn.Sequential(5 nn.Linear(64, 128),6 nn.BatchNorm1d(128), # normalise each batch's activations7 nn.ReLU(),8 nn.Dropout(p=0.3), # randomly zero 30% during training9 nn.Linear(128, 10),10)11 12model.train() # dropout on, batch stats used13out_train = model(torch.randn(32, 64))14model.eval() # dropout off, running stats used15out_eval = model(torch.randn(1, 64))1/4BatchNorm rescales the 128 outputs using the current batch's mean and spread.
BatchNorm and Dropout inside a small PyTorch model, plus the mode switch that changes how both behave.
Save yourself the pain
Common mistakes
Oops
Forgetting model.eval() before making predictions.
Do this instead
Call model.eval() for validation and inference, and model.train() before going back to training.
Oops
Setting dropout to 0.8 everywhere to fight overfitting.
Do this instead
Start around 0.2 to 0.5 on large dense layers. Too much dropout makes the model underfit.
Your mission
Overfit, then fix it
Quick check
Why does dropout get switched off at prediction time?
Go deeper
- 1Add dropout to a network and observe the effect on the train/validation performance gap.
- 2Learn where batch normalization layers are typically placed in a network.
- 3Compare training stability and speed with and without batch normalization.
More topics at this stop
 Neural Network Basics
 Activation Functions
 Backpropagation & Gradient Descent
 Building Networks With TensorFlow / Keras
 Building Networks With PyTorch
 Convolutional Neural Networks (CNNs)
 Recurrent Neural Networks (RNNs) & LSTMs
 Transfer Learning
 GPUs & Training Basics

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
