In short
Training a vision model from zero can take millions of images. With transfer learning you borrow a model that already knows how to see, and teach it your task with a few hundred photos.
Reusing a model already trained on a large dataset (like ImageNet) and fine-tuning it on your smaller, specific dataset — dramatically reduces the data and compute needed for strong results.
Think of it like this
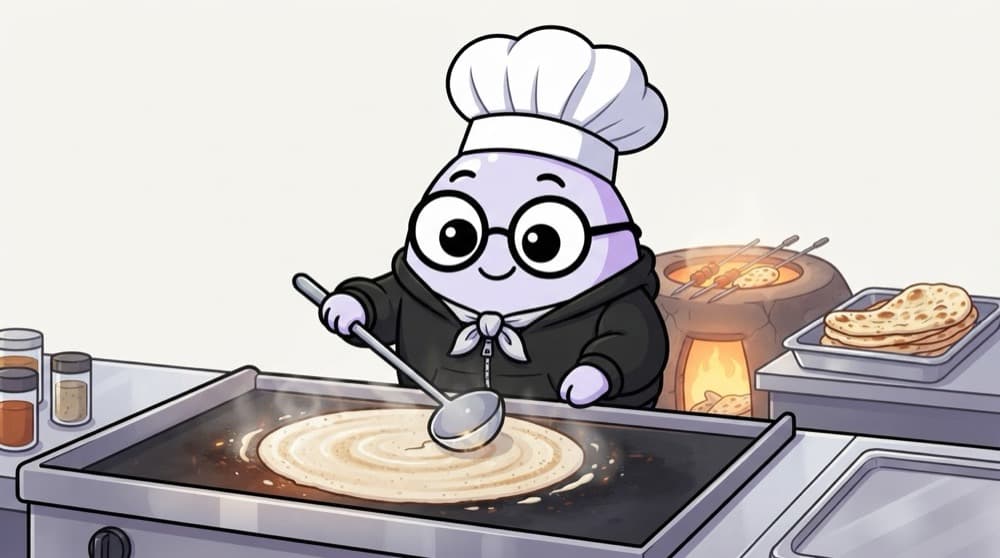
The dhaba cook learns dosa
A cook from a Punjabi dhaba joins a South Indian restaurant. They don't relearn knife skills, heat control or timing. They only learn the new dishes. In a week they're making good dosas. The general skills carried over, and only the specifics were new.
Watch it happen
Reusing a pretrained image model
1/5Load a model trained on a huge dataset like ImageNet, without its final classification layer.
The big ideas
What you need to know
Features transfer
Edges, textures and shapes are useful for almost any image task, so early layers rarely need retraining.
Small data works
A few hundred labelled images per class can be enough when you start from a strong pretrained base.
Tiny learning rate to fine-tune
Big updates would wreck the pretrained weights. Fine-tune with a rate around 10 to 100 times smaller.
Same idea for text
Pretrained language models like BERT are reused for sentiment or spam the same way.
See it in code
Walk through the code
1import keras2from keras import layers3 4base = keras.applications.MobileNetV2(5 input_shape=(160, 160, 3), include_top=False, weights="imagenet")6base.trainable = False # freeze learned features7 8inputs = keras.Input(shape=(160, 160, 3))9x = keras.applications.mobilenet_v2.preprocess_input(inputs)10x = base(x, training=False)11x = layers.GlobalAveragePooling2D()(x)12outputs = layers.Dense(2, activation="softmax")(x)13model = keras.Model(inputs, outputs)14model.compile(optimizer="adam", loss="sparse_categorical_crossentropy", metrics=["accuracy"])1/4Download pretrained weights and drop the original 1,000-class top layer.
MobileNetV2 trained on ImageNet becomes the base for a new two-class classifier. Only the last Dense layer learns at first.
Save yourself the pain
Common mistakes
Oops
Unfreezing everything right away with a normal learning rate.
Do this instead
Train the new head first. Then unfreeze a few top layers and use a much smaller learning rate.
Oops
Skipping the base model's own preprocessing.
Do this instead
Use the matching preprocess_input. Pretrained weights expect pixels scaled the same way as in their training.
Your mission
Two-class classifier from your phone
Quick check
Why freeze the pretrained base at first?
Go deeper
- 1Fine-tune a pretrained image model (e.g. ResNet) on a small custom dataset.
- 2Learn the difference between feature extraction and full fine-tuning.
- 3Understand why transfer learning is the default approach for most real-world deep learning projects.
More topics at this stop
 Neural Network Basics
 Activation Functions
 Backpropagation & Gradient Descent
 Building Networks With TensorFlow / Keras
 Building Networks With PyTorch
 Convolutional Neural Networks (CNNs)
 Recurrent Neural Networks (RNNs) & LSTMs
 Regularization in Deep Learning (Dropout, Batch Norm)
 GPUs & Training Basics

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
