Convolutional Neural Networks (CNNs)
Part of the Data Science Roadmap
In short
A photo has millions of pixels, far too many for plain dense layers. CNNs slide small pattern detectors across the image, which is why they power so much of computer vision.
A network architecture specialized for image data — convolutional layers detect local patterns (edges, textures) that combine into higher-level features as you go deeper into the network.
Think of it like this
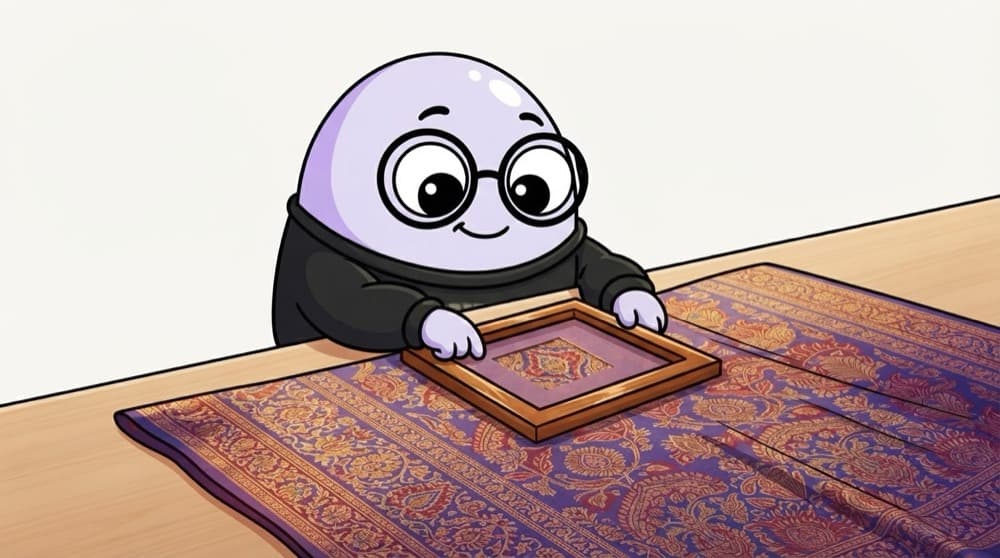
Checking a saree for flaws
A weaver checks a long saree by sliding a small square frame over it, one patch at a time, looking for the same kinds of flaws everywhere. She doesn't stare at the whole six yards at once. A CNN filter is that small frame.
Watch it happen
A 3-wide edge filter sliding over a row of pixels
1/5One row of pixels: dark, then bright, then dark. The filter is [-1, 0, 1], a simple edge detector.
The big ideas
What you need to know
Filters share weights
One small filter scans the whole image, so a CNN needs far fewer weights than a dense layer.
Pooling shrinks
Max pooling keeps the strongest response in each small patch, making the map smaller and a bit shift-tolerant.
Patterns build up
Early layers find edges, middle layers find textures and parts, deep layers respond to whole objects.
Beyond photos
1D convolutions work on audio and sensor signals, and similar ideas show up in some text models.
See it in code
Walk through the code
1import keras2from keras import layers3 4model = keras.Sequential([5 keras.Input(shape=(32, 32, 3)),6 layers.Conv2D(32, 3, activation="relu"),7 layers.MaxPooling2D(),8 layers.Conv2D(64, 3, activation="relu"),9 layers.MaxPooling2D(),10 layers.Flatten(),11 layers.Dense(10, activation="softmax"),12])13model.summary()1/4Input is height, width and 3 colour channels.
A small CNN for 32 by 32 colour images, the size used in the free CIFAR-10 dataset.
Save yourself the pain
Common mistakes
Oops
Flattening a big image straight into a Dense layer.
Do this instead
Use conv and pooling layers first. They cut the size and keep the spatial patterns.
Oops
Training a CNN from scratch on 200 photos.
Do this instead
With little data, use transfer learning from a pretrained model instead.
Your mission
Train on CIFAR-10
Quick check
Why does a CNN need far fewer weights than a dense network on images?
Go deeper
- 1Read a visual explainer of how a convolution operation slides over an image.
- 2Build a simple CNN for image classification on a small dataset (e.g. MNIST).
- 3Learn the roles of pooling layers and why they reduce spatial dimensions.
More topics at this stop
 Neural Network Basics
 Activation Functions
 Backpropagation & Gradient Descent
 Building Networks With TensorFlow / Keras
 Building Networks With PyTorch
 Recurrent Neural Networks (RNNs) & LSTMs
 Transfer Learning
 Regularization in Deep Learning (Dropout, Batch Norm)
 GPUs & Training Basics

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
