Building Networks With PyTorch
Part of the Data Science Roadmap
In short
PyTorch is the favourite of researchers and many companies because you write the training loop yourself. More code, but you see and control every step.
Meta's deep learning framework — more explicit and 'Pythonic' than Keras, and the dominant choice in research and increasingly in industry.
Think of it like this
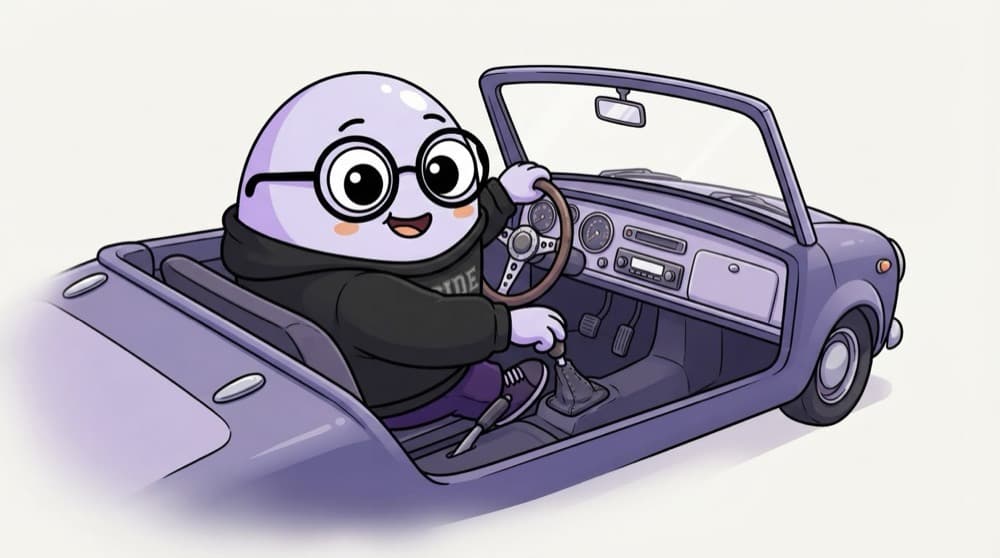
Driving a manual car
An automatic car changes gears for you. A manual car makes you press the clutch and shift every gear yourself. It's more work, but you control exactly what happens. Keras is the automatic. In PyTorch, you shift the gears.
Watch it happen
The PyTorch training loop
1/5Clear old gradients. PyTorch adds gradients up by default, so skipping this mixes batches.
The big ideas
What you need to know
Tensors
Tensors are like NumPy arrays that can live on a GPU and remember how they were computed.
Autograd
PyTorch records operations as they run and computes gradients for you when you call backward().
nn.Module
Build models from nn.Sequential, or write a class with your own forward() method for full control.
DataLoader
Wraps your dataset to give shuffled mini-batches, so the loop stays simple.
See it in code
Walk through the code
1import torch2from torch import nn3 4X = torch.randn(256, 10)5y = (X.sum(dim=1, keepdim=True) > 0).float() # toy labels6 7model = nn.Sequential(nn.Linear(10, 32), nn.ReLU(), nn.Linear(32, 1))8loss_fn = nn.BCEWithLogitsLoss()9opt = torch.optim.Adam(model.parameters(), lr=1e-2)10 11for epoch in range(50):12 opt.zero_grad()13 loss = loss_fn(model(X), y)14 loss.backward()15 opt.step()16print(loss.item())1/3256 random rows. The label is 1 when the row's values add up to more than zero.
A tiny yes/no classifier with the full loop written out. The loss should drop well below its starting value.
Save yourself the pain
Common mistakes
Oops
Forgetting opt.zero_grad() inside the loop.
Do this instead
Clear gradients every iteration, or they pile up from earlier batches and the updates go wrong.
Oops
Evaluating with dropout still active and gradients still tracked.
Do this instead
Call model.eval() and wrap evaluation in torch.no_grad() to switch off dropout and save memory.
Your mission
Port MNIST to PyTorch
Quick check
In a PyTorch loop, what does loss.backward() do?
Go deeper
- 1Build the same simple network from the Keras exercise, now in PyTorch.
- 2Learn PyTorch's explicit training loop (forward pass, loss, backward pass, optimizer step).
- 3Compare the developer experience between TensorFlow/Keras and PyTorch directly.
More topics at this stop
 Neural Network Basics
 Activation Functions
 Backpropagation & Gradient Descent
 Building Networks With TensorFlow / Keras
 Convolutional Neural Networks (CNNs)
 Recurrent Neural Networks (RNNs) & LSTMs
 Transfer Learning
 Regularization in Deep Learning (Dropout, Batch Norm)
 GPUs & Training Basics

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
