GPUs & Training Basics
Part of the Data Science Roadmap
In short
Training on a laptop CPU can take hours. The same job on a GPU may finish in minutes. Knowing why, and how to use free GPUs, saves you a lot of waiting.
Understanding why deep learning relies on GPUs (massively parallel matrix operations), and the basics of batch size, epochs, and training time trade-offs when working with limited compute.
Think of it like this
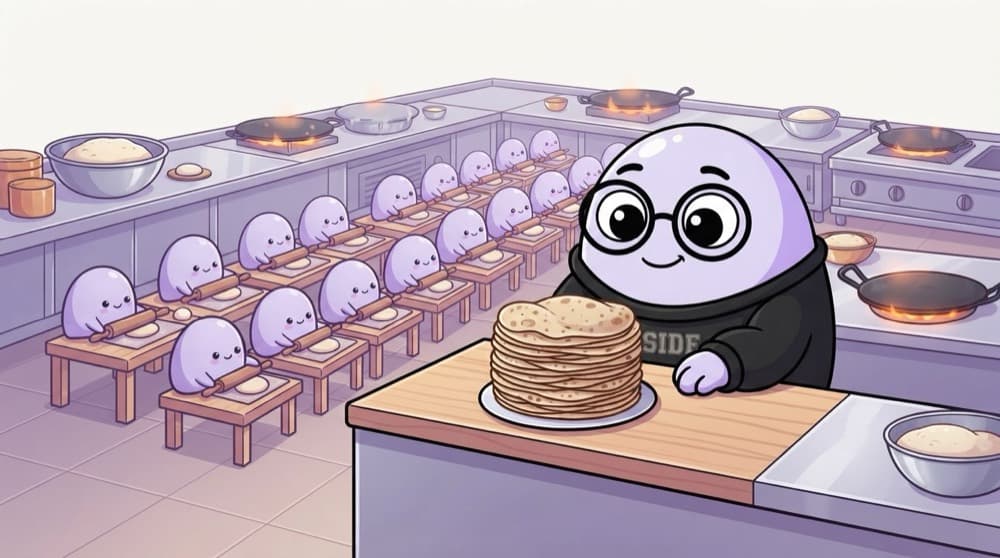
One master chef vs a langar kitchen
One master chef can cook anything, but makes rotis one at a time. A community kitchen has a hundred volunteers rolling rotis side by side. Each does a simple job, all at once. A CPU is the master chef. A GPU is the hundred volunteers.
Watch it happen
CPU vs GPU for training
CPU
- Few powerful cores
- Great at varied, step-by-step work
- Fine for small models and data prep
GPU
- Thousands of simple cores
- Huge matrix maths in parallel
- Big speed-up for deep learning
Neural network training is mostly matrix multiplication, which GPUs do in parallel. Use a GPU for deep learning, a CPU for everything else.
The big ideas
What you need to know
Move model and data
Both the model and each batch must sit on the same device, or PyTorch throws an error.
Batch size vs memory
Bigger batches use more GPU memory. If you get 'out of memory', halve the batch size.
Mixed precision
Training in 16-bit floats where safe can speed things up and save memory on modern GPUs.
Free GPUs exist
Google Colab and Kaggle notebooks offer free GPU time with usage limits. Good enough for learning.
See it in code
Walk through the code
1import torch2 3device = "cuda" if torch.cuda.is_available() else "cpu"4print("training on", device)5 6model = torch.nn.Linear(1000, 10).to(device)7x = torch.randn(512, 1000, device=device)8 9out = model(x) # runs on the GPU if there is one10print(out.device)1/3Use the NVIDIA GPU if PyTorch can see one, otherwise fall back to CPU.
The standard device check. On Apple Silicon Macs, 'mps' is the GPU option instead of 'cuda'.
Save yourself the pain
Common mistakes
Oops
Moving the model to the GPU but leaving batches on the CPU.
Do this instead
Call .to(device) on every batch inside the loop, or build the tensors on the device directly.
Oops
Leaving a paid cloud GPU running overnight by accident.
Do this instead
Stop or delete cloud GPU machines when done, and set billing alerts. Free notebooks are safer for practice.
Your mission
Time CPU vs GPU
Quick check
Why are GPUs so much faster for training neural networks?
Go deeper
- 1Train the same small model on CPU versus GPU (e.g. via Colab) and compare training time.
- 2Learn how batch size affects both training speed and memory usage.
- 3Understand why free/cheap GPU access (Colab, Kaggle) is usually enough for learning projects.
More topics at this stop
 Neural Network Basics
 Activation Functions
 Backpropagation & Gradient Descent
 Building Networks With TensorFlow / Keras
 Building Networks With PyTorch
 Convolutional Neural Networks (CNNs)
 Recurrent Neural Networks (RNNs) & LSTMs
 Transfer Learning
 Regularization in Deep Learning (Dropout, Batch Norm)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
