Evaluating Fine-Tuned Models
Part of the AI Engineer Roadmap
In short
Your fine-tuned model sounds great in three demo chats. But is it actually better than the base model, and did it forget anything? Without a proper evaluation, you're guessing.
Measuring whether a fine-tuned model actually improved on the target task without regressing on general capability — requires task-specific metrics plus qualitative review.
Think of it like this
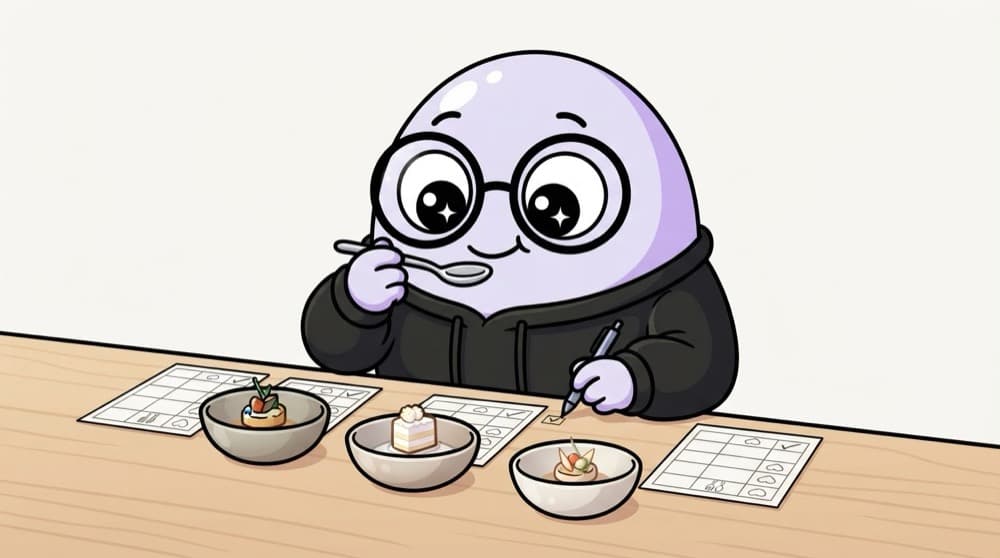
The wedding food tasting
Before the wedding, the family sits down for a tasting. Each dish gets tried and scored: taste, spice, temperature. They also check old favourites didn't get worse. Evaluating a fine-tuned model is that tasting, done before the big day.
Watch it happen
What to check before shipping
1/5Always compare against a baseline: the base model with your best prompt.
The big ideas
What you need to know
Beat the baseline
If a good prompt on the base model scores the same, the fine-tune isn't worth maintaining.
Never peek at the test set
Don't tune on test examples. Use a separate validation set for choosing settings.
LLM-as-judge with care
Judges can favour longer answers or their own style. Give a rubric and spot-check with humans.
Track over time
Save scores per model version so you can see whether a change helped or hurt.
See it in code
Walk through the code
1import json2 3def evaluate(generate, test_path="test.jsonl"):4 rows = [json.loads(l) for l in open(test_path)]5 correct = 06 for r in rows:7 pred = generate(r["prompt"]).strip().upper()8 correct += pred == r["label"].upper()9 return correct / len(rows)10 11base = evaluate(lambda p: base_model_reply(p))12tuned = evaluate(lambda p: tuned_model_reply(p))13print(f"base: {base:.1%} tuned: {tuned:.1%}")1/3Load a held-out test file with prompts and expected labels.
A minimal exact-match evaluation that compares base and fine-tuned models on the same held-out file.
Save yourself the pain
Common mistakes
Oops
Judging a fine-tune from a handful of chats.
Do this instead
Use at least 50 to 100 held-out examples and a clear metric, compared with the base model.
Oops
Only measuring the task you trained on.
Do this instead
Also check a few unrelated tasks. Forgetting general skills is a common side effect.
Your mission
Build a mini eval
Quick check
Your fine-tuned model scores 92 percent on your test set. What should you check before celebrating?
Go deeper
- 1Build a small evaluation set separate from training data and score before/after fine-tuning.
- 2Combine automated metrics with manual review of real outputs.
- 3Check for regressions on tasks outside the fine-tuning focus, not just the target task.
More topics at this stop
 Full Fine-Tuning vs PEFT
 LoRA & QLoRA
 Instruction Tuning
 RLHF (Overview)
 DPO (Overview)
 Dataset Preparation for Fine-Tuning
 Model Quantization
 Model Distillation

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
