Descriptive Statistics
Part of the AI Engineer Roadmap
In short
Before any model, you summarise the data: what's typical, how spread out it is, what's odd. Five or six numbers can tell you whether a dataset is sane or full of surprises.
Mean, median, mode, variance, standard deviation and percentiles — the first thing you compute on any dataset before modeling it.
Think of it like this
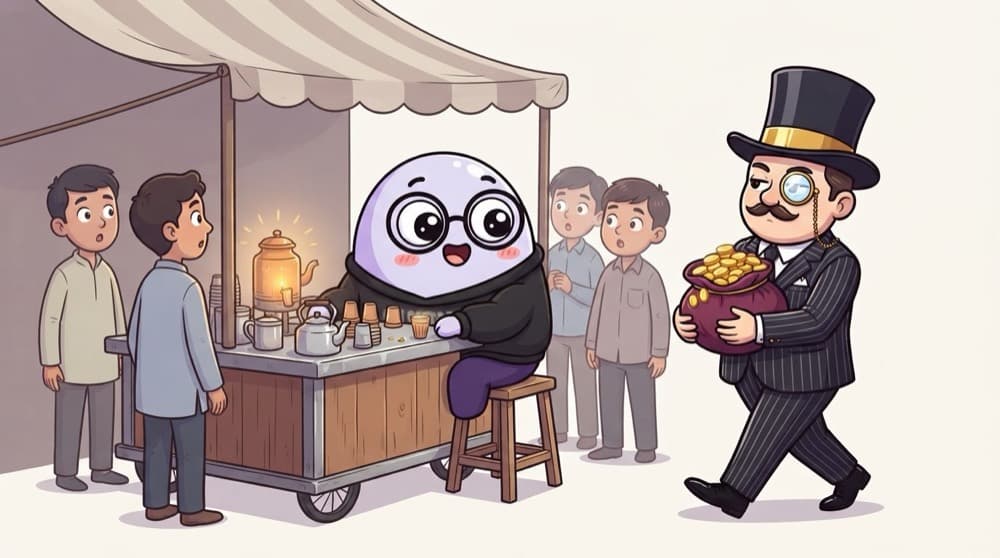
A billionaire at the chai stall
Five regulars at a chai stall earn about ₹15,000 a month each. A billionaire stops for chai. Suddenly the average income at the stall is in crores, yet nobody else got richer. The median, the middle person, still says ₹15,000. Pick the summary that tells the truth.
Watch it happen
Monthly income in ₹ thousands
1/5Six people, already sorted. One value, 500, is far from the rest. That's an outlier.
The big ideas
What you need to know
Centre: mean, median, mode
Mean uses every value, so outliers drag it. Median is the middle and ignores extremes. Mode is the most frequent.
Spread: variance and std
Standard deviation is the typical distance from the mean, in the same units as the data.
Percentiles and IQR
The 25th and 75th percentiles bracket the middle half. Their gap, the IQR, isn't fooled by outliers.
df.describe() does it all
In pandas, one call gives count, mean, std, min, quartiles and max for every numeric column.
See it in code
Walk through the code
1import numpy as np2from statistics import mode3 4incomes = np.array([12, 15, 15, 18, 20, 500]) # ₹ thousand / month5 6print(incomes.mean().round(2)) # 96.67 dragged up by 5007print(np.median(incomes)) # 16.58print(mode(incomes.tolist())) # 159print(incomes.std().round(1)) # about 180, the outlier inflates it10print(np.percentile(incomes, [25, 75])) # [15. 19.5]1/3Five ordinary incomes and one extreme one.
Mean and standard deviation both react strongly to the 500. Median and percentiles barely notice it.
Save yourself the pain
Common mistakes
Oops
Reporting only the mean for skewed data like salaries or house prices.
Do this instead
Report the median too, or instead. Show both when they differ a lot.
Oops
Deleting every outlier because it 'looks wrong'.
Do this instead
Check it first. Some outliers are typos, others are the most important rows in the data.
Your mission
Summarise a real dataset
Quick check
House prices in a city have a few huge mansions. Which number best describes a typical house?
Go deeper
- 1Compute descriptive statistics by hand on a small dataset, then verify with pandas.
- 2Learn when mean vs median is the better summary (skewed vs symmetric data).
- 3Practice interpreting variance and standard deviation on real data.
More topics at this stop
 Linear Algebra Basics (Vectors, Matrices)
 Matrix Operations
 Eigenvalues & Eigenvectors
 Calculus Basics (Derivatives, Gradients)
 Chain Rule
 Partial Derivatives
 Probability Fundamentals
 Probability Distributions
 Bayes' Theorem
 Hypothesis Testing
 Correlation vs Causation
 Optimization Basics (Gradient Descent)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
