In short
Real models have thousands or billions of weights. A partial derivative asks how the loss changes when you nudge one weight and freeze the rest. Do that for every weight and you have the gradient.
Derivatives with respect to one variable while holding others constant — how gradient descent computes how much to adjust each individual weight.
Think of it like this
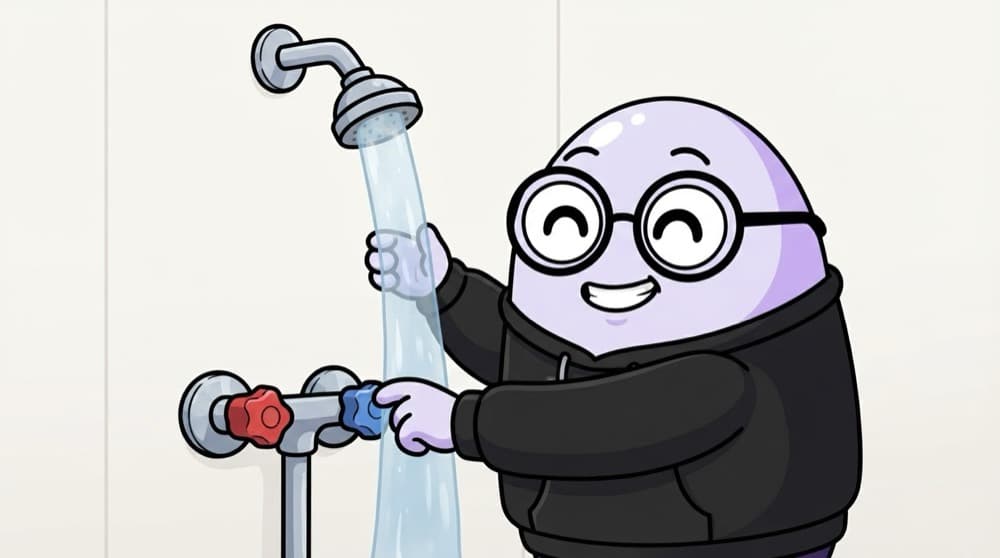
Two knobs on the shower
The water is too cold. If you twist both knobs together, you can't tell which one helped. So you turn only the hot knob and feel the change, then try only the cold one. Each test is a partial derivative: one knob moves, the other stays put.
Watch it happen
Loss for pred = w1·x + w2, x = 2, y = 7
1/4With w1 = 1 and w2 = 1, the prediction is 3, the error is −4 and the loss is 16.
The big ideas
What you need to know
One variable at a time
Written ∂L/∂w1. Treat every other variable as a fixed number and differentiate as usual.
Stack them into a gradient
The gradient ∇L is the list of all partial derivatives, one slot per weight.
Bigger partial, bigger update
Weights with large partials get pushed more in each gradient descent step. Ones near zero barely move.
One backward pass gets all of them
Backprop computes every partial derivative in roughly the cost of one extra forward pass.
See it in code
Walk through the code
1x, y = 2.0, 7.02w1, w2 = 1.0, 1.03 4def loss(w1, w2):5 pred = w1 * x + w26 return (pred - y) ** 27 8err = (w1 * x + w2) - y # -4.09dL_dw1 = 2 * err * x # -16.010dL_dw2 = 2 * err # -8.011 12h = 1e-5 # numeric check: nudge one at a time13print((loss(w1 + h, w2) - loss(w1 - h, w2)) / (2 * h)) # about -1614print((loss(w1, w2 + h) - loss(w1, w2 - h)) / (2 * h)) # about -81/3Squared error loss for a one-feature linear model.
Each numeric check nudges one weight and leaves the other alone. That is exactly what a partial derivative means.
Save yourself the pain
Common mistakes
Oops
Changing all weights at once and trying to read off each one's effect.
Do this instead
A partial derivative moves one variable while freezing the rest. Mixing them hides which one mattered.
Oops
Forgetting that a partial is only true at the current point.
Do this instead
Recompute partials after each update. The slope changes as the weights change.
Your mission
Train a two-weight model by hand
Quick check
L = 3·a + a·b. What is ∂L/∂b?
Go deeper
- 1Compute partial derivatives of a multi-variable function by hand.
- 2Connect partial derivatives to gradient vectors used in optimization.
- 3Practice on a simple loss function with two parameters.
More topics at this stop
 Linear Algebra Basics (Vectors, Matrices)
 Matrix Operations
 Eigenvalues & Eigenvectors
 Calculus Basics (Derivatives, Gradients)
 Chain Rule
 Probability Fundamentals
 Probability Distributions
 Bayes' Theorem
 Descriptive Statistics
 Hypothesis Testing
 Correlation vs Causation
 Optimization Basics (Gradient Descent)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
