In short
Conversions went from 4.1% to 4.4%. Real improvement or random wobble? Hypothesis testing is the standard way to decide, instead of going with whoever argues loudest.
The statistical framework (p-values, significance levels, t-tests) for deciding whether an observed effect is real or due to chance — used in A/B testing model changes.
Think of it like this
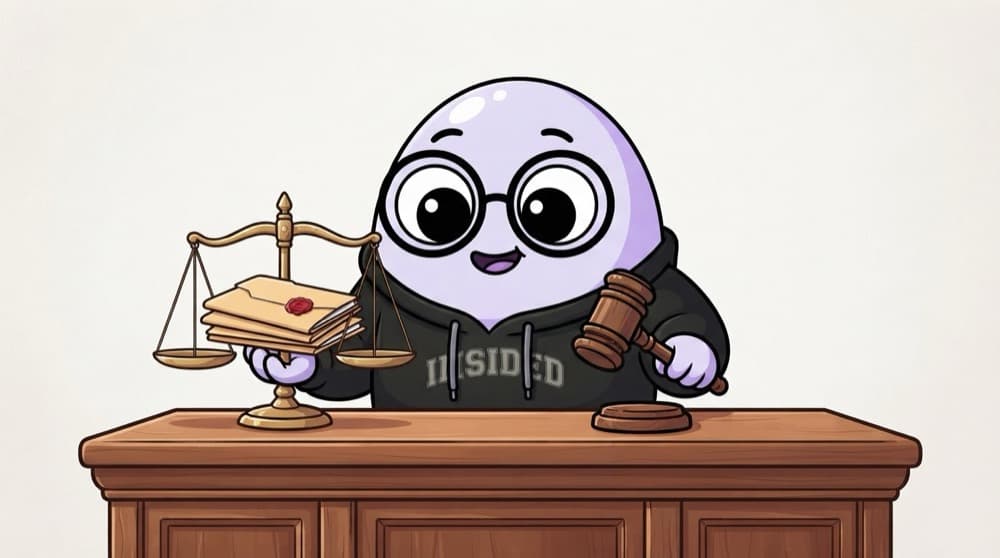
Innocent until proven guilty
A court starts by assuming the accused is innocent. Only strong evidence lets the judge reject that. Hypothesis testing works the same way: assume 'no effect' first, and only reject it if the data would be very surprising under that assumption.
Watch it happen
The steps of a test
1/6Null (H0): the new button changes nothing. Alternative (H1): it changes the conversion rate.
The big ideas
What you need to know
Null vs alternative
The null says 'nothing is going on'. You look for evidence strong enough to reject it.
Type I error
Rejecting a true null: a false alarm. Alpha is the rate you accept for this.
Type II error
Missing a real effect. Usually caused by too small a sample.
Pick the right test
t-test for means, chi-square for counts and categories, z-test for proportions with big samples.
See it in code
Walk through the code
1from scipy import stats2 3control = [42, 38, 45, 40, 39, 44, 41] # minutes on page4treatment = [47, 44, 49, 46, 43, 48, 45]5 6t_stat, p_value = stats.ttest_ind(treatment, control, equal_var=False)7print(round(t_stat, 2), round(p_value, 4))8 9if p_value < 0.05:10 print("Reject H0: the difference is unlikely to be chance")11else:12 print("Fail to reject H0")1/3Two groups of measurements. Tiny here just to show the idea.
A Welch's t-test comparing two small groups. Real tests need far more data, planned in advance.
Save yourself the pain
Common mistakes
Oops
Saying 'we proved there is no difference' when p > 0.05.
Do this instead
Say 'we didn't find enough evidence of a difference'. A small sample can easily miss a real effect.
Oops
Choosing the test or the threshold after seeing the results.
Do this instead
Decide hypothesis, test and alpha up front, and write them down.
Your mission
Run a test in a sheet
Quick check
Your test gives p = 0.21. What's the correct conclusion?
Go deeper
- 1Learn the logic of null vs. alternative hypotheses and p-values.
- 2Run a simple t-test in Python (scipy.stats) on two sample groups.
- 3Understand common pitfalls: p-hacking, misinterpreting p-values.
More topics at this stop
 Linear Algebra Basics (Vectors, Matrices)
 Matrix Operations
 Eigenvalues & Eigenvectors
 Calculus Basics (Derivatives, Gradients)
 Chain Rule
 Partial Derivatives
 Probability Fundamentals
 Probability Distributions
 Bayes' Theorem
 Descriptive Statistics
 Correlation vs Causation
 Optimization Basics (Gradient Descent)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
