In short
Fine-tuning on examples teaches a model what good answers look like. RLHF goes further: people compare answers, and the model learns to prefer what humans rate better. It's a big reason chat assistants feel helpful.
Reinforcement Learning from Human Feedback — training a model using human preference rankings to better align its outputs with what people actually want — the technique behind ChatGPT-style alignment.
Think of it like this
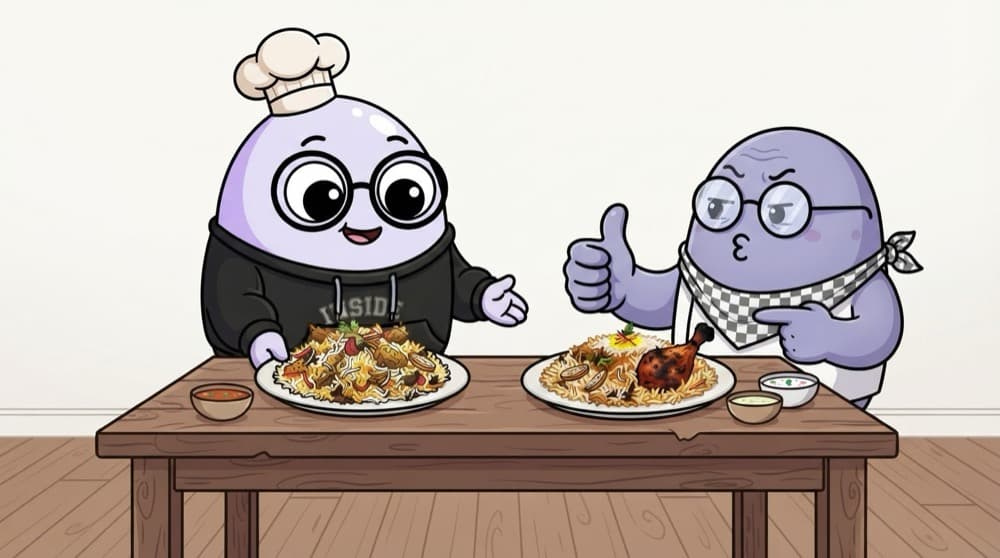
The cooking contest judge
A young chef cooks two versions of biryani. The judge tastes both and says, 'This one is better.' After hundreds of rounds, the chef learns what judges like, even for dishes they never judged. RLHF trains a model the same way, with a 'judge' model learned from human ratings.
Watch it happen
The classic RLHF recipe
1/5Start from an instruction-tuned model.
The big ideas
What you need to know
Comparisons are easier
People find 'A is better than B' easier and more consistent than writing perfect answers from scratch.
Reward model as judge
A separate model learns human taste, so RL can score millions of answers without a human each time.
Stay close to the start
A KL penalty keeps the model near the original, so it doesn't drift into weird text that tricks the reward model.
Reward hacking
Models can learn to please the judge, for example by being long-winded, without really improving. Needs careful checks.
Save yourself the pain
Common mistakes
Oops
Thinking RLHF teaches the model new facts.
Do this instead
It mainly shapes style and behaviour: helpfulness, tone, refusals. Knowledge comes from pretraining.
Oops
Trying full RLHF with PPO as a first student project.
Do this instead
It's complex and unstable. Try DPO on a small preference dataset first; it's far simpler.
Your mission
Be the labeller
Quick check
What is the reward model's job in RLHF?
Go deeper
- 1Read a high-level explainer of the three RLHF stages: SFT, reward model, RL fine-tuning.
- 2Understand why RLHF is expensive and requires substantial human-labeled preference data.
- 3Learn how DPO emerged as a simpler alternative to full RLHF.
More topics at this stop
 Full Fine-Tuning vs PEFT
 LoRA & QLoRA
 Instruction Tuning
 DPO (Overview)
 Dataset Preparation for Fine-Tuning
 Model Quantization
 Model Distillation
 Evaluating Fine-Tuned Models

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
